Domain01
Responsible AI + Intelligent Products
AI-assisted products that show what the system is doing, keep people in control, and support better decisions.
- Responsible AI
- Agentic Workflows
- Decision Support
I'm a principal product designer who turns complex problems into clear, accessible workflows and scalable product systems. I work across research, interaction design, system design, and implementation, especially in enterprise software, responsible AI, and products where clarity, control, and reliability are critical.
Where I Create Value
AI-assisted products that show what the system is doing, keep people in control, and support better decisions.
Consumer products built around discovery, creation, identity, and community.
Data-heavy products and workflows that help expert users work faster with clearer, more consistent systems.
Designed and built a full-stack PHP/MySQL connected commerce platform—integrating custom APIs to support custom product discovery, live preview, payment, engraving, and automated fulfillment.
One connected system for custom merchandise, from product discovery and live preview through approval, laser production, and fulfillment.
KPop-Swag.com sells personalized, laser-engraved merchandise. Customization adds work before and after checkout. Customers need to know what the product will look like. Operators need accurate production instructions. Staff need the same order context through approval, engraving, shipping, and communication.
My role: I was the full-stack product designer and developer. I handled research, product definition, customer and staff workflows, the design system, implementation, service integrations, testing, and deployment.
Each stage adds to the same order and saved design, so the customer's choices stay available through approval, production, and fulfillment.
Products, materials, prices, and customization options.
Artwork, text, side, placement, scale, and orientation.
Product geometry, engraving simulation, and protected regions.
Saved design state and a shared visual reference.
Operator-ready artwork, specifications, and job status.
Payment, label, tracking, and customer communication.
More than 20 conversations with K-pop fans at live events showed which problems customers actually noticed. I turned those findings into product and interaction requirements.
Customization confidence mattered before checkout. The response was an editable Studio, product-specific boundaries, and a preview that preserves the approved composition.
Total cost visibility mattered more than shaving another step from checkout. Shipping estimates and pricing clarity were moved earlier in the checkout flow.
Registration could interrupt a first purchase. Guest checkout became the default low-friction path, with account benefits introduced after commitment.
The hardest decisions connected what customers expected with what production and staff workflows could actually support.
A text field or static mockup couldn't communicate placement, side, scale, orientation, or material behavior.
I built a product-aware Studio and interactive 3D preview that use the same saved design data.
The customer, approver, and operator see the same saved composition.
A universal admin interface exposed irrelevant complexity and increased the risk of sensitive actions.
I designed focused workspaces for customers, staff, laser operators, and superadmins, supported by route-level permissions.
Each role sees the information and actions required for its next decision without carrying the entire system.
Payment, production, shipping, and communication could easily fragment into separate tools and status models.
I kept approval, production jobs, labels, tracking, and notifications attached to the same order record.
Staff can move an order forward without re-entering specifications or losing the customer and design context.
An eight-week build could accumulate inconsistent forms, states, validation, and accessibility behavior.
I created reusable components and behavior contracts while building features, then used the same patterns across commerce and operations.
New workflows reuse the same interaction, validation, focus, and visual rules.
The platform supports five permission levels. Each role gets the navigation, information, and actions needed for its job while sharing the same order data.
Browse, customize, preview, understand cost, and complete a purchase with or without creating an account.
See prioritized jobs with the product, artwork, side, quantity, production notes, and status controls in one working view.
Manage orders, review customization, generate labels, communicate with customers, and resolve fulfillment exceptions.
Control roles, approve sensitive promotions, manage service configuration, and distinguish test from live environments.
Preserve shared state, validate transitions, timestamp operational events, and trigger the appropriate notifications.
Keep states, controls, validation, accessibility, and responsive behavior consistent across every workspace.
The work after checkout determines whether the product is made correctly and delivered on time. I designed the production and fulfillment tools with the same care as the storefront.
Operators receive complete, prioritized job specifications with direct start, hold, and completion actions.
Staff can inspect customer, payment, design, production, shipping, and communication context without changing systems.
EasyPost rate selection, label generation, tracking persistence, and customer notification stay attached to the order.
Coupon rules support product restrictions, BOGO behavior, expiration, and approval when business oversight is required.
Sensitive service settings use validation, masked values, environment indicators, permissions, and re-authentication.
Validation and status feedback make incomplete data, integration failures, and blocked transitions visible before they become fulfillment errors.
Because I designed and built the platform, I could enforce interaction rules in the product instead of leaving them in handoff notes. I defined accessibility, validation, permissions, and security with each workflow.
I built keyboard operation, visible focus, modal focus management, semantic labels, live status messaging, contrast, and reduced-motion behavior into reusable components.
Server-side validation, prepared queries, CSRF protection, secure sessions, password hashing, and rate limiting protect transactional workflows.
Route-level permissions, encrypted credentials, masked keys, re-authentication, and clear test/live modes reduce operational risk.
The product connects customer-facing commerce with the staff and operator workflows needed to make and ship personalized products.
The approved design, product geometry, transforms, and constraints travel together from Studio into production.
Each role receives the context and controls needed for its part of the lifecycle.
Shared components, permissions, and saved-state rules can support additional products and workflows.
For custom commerce, the experience continues after payment. Production accuracy, exception handling, and communication are part of the customer promise.
A consistent record across preview, approval, production, and fulfillment keeps people from re-entering or reinterpreting the same information.
Building the data model and application exposed edge cases early and let me turn design decisions into working product rules.
What I did: I took the product from an unclear idea through research, customer and staff workflows, implementation, testing, and production.
This was my first end-to-end solo product, from idea to production in under eight weeks. I owned the design and development decisions, and used AI to help organize notes and speed up implementation.
Figma, Photoshop, Illustrator; Three.js for 3D preview; PHP/MySQL for interactive mockups; custom design system built from scratch
PHP, MySQL, JavaScript, Stripe, EasyPost, and Brevo APIs; Codex for coding and QA; AI to organize handwritten specs into Markdown
20+ customer conversations, usability and operator testing; AI helped organize my notes and I reviewed the source material myself
Role: Solo IC. I created the specs, designs, and product decisions. AI helped organize notes and speed up implementation, and I reviewed the output.
How I led a high-stakes product concept through a major reorganization, using research to reset a fragmented renewals vision and give leadership a clearer basis for investment.
Turning a fragmented renewal workflow into a product concept leadership could evaluate and fund
Workday was evaluating a subscription management product while its own renewal teams still worked across Salesforce, quoting tools, spreadsheets, and Word documents. The concept needed to connect account review, subscription changes, pricing, quotes, and contracts into one workflow.
The stage gate was about helping leadership decide whether the product was worth funding. We needed enough research, workflow detail, and working UI to show what the product could be and how it would help.
I led the design direction, worked with the researcher on the primary persona and renewal process, defined the core workflow, and built the interactive concept used in the funding review.
Led early concept work and turned an unclear opportunity into a workflow the team could discuss and test.
Worked with the researcher to define the primary persona, map the renewal steps, and identify the biggest workflow problems.
Built the mockups and flow leadership needed to understand the product and decide whether to invest.
As the business case changed, I kept checking the concept against the research. When the direction started reflecting current platform limits more than user needs, I recommended a reset and rebuilt the flow around the evidence.
Renewal specialists moved between Salesforce, quoting tools, spreadsheets, and Word documents just to create and check a quote. The work was slow, easy to get wrong, and hard to keep track of.
Workday didn't have one subscription management product, so users pieced the workflow together from other tools.
Pricing changes and contract edits required repeated copying, checking, and cleanup.
Users had to move between systems just to gather context, configure the renewal, and prepare customer-facing materials.
Because this was a new market for Workday, external recruiting was difficult. We used Workday's own subscription operations as a proxy and spoke with a Sales Ops Manager, Subscription Manager, and Renewal Specialist.
The research was enough to define a primary persona, map the quote-to-renewal steps, and identify the main workflow problems.
We centered the concept on a subscription manager who needed clearer account status, faster modeling, and less manual work.
Mapping the steps showed that the work spanned the full quote-to-renewal process.
The concept started with the account, then followed the main jobs: assess, amend, model, and generate a quote.
Changes to the business case had pushed the concept toward dense tables, extra navigation, and current platform limits. The new concept was starting to repeat the same fragmented workflow we had found in research.
Three days before the executive review, I recommended a reset. The researcher and I revisited the research, simplified the flow, and rebuilt the clickable concept around the work users actually needed to do.
The concept was getting denser while the product story was getting harder to follow.
I stopped designing around current platform limits and rebuilt the flow around the intended product.
The rebuilt concept gave leadership a clear account-to-renewal flow they could evaluate.
The reset concept started with a renewal dashboard, then moved into account detail and subscription modeling. Users could see account health, subscription status, opportunity signals, and the actions needed to move the renewal forward without reconstructing the story across several tools.
A portfolio view with key metrics and drill-down detail so managers could start with the accounts that needed attention.
Customizable views, clearer status, and product-family grouping made account review easier.
A visual builder let users start from an existing subscription, apply pricing rules, and explore changes over time.
Research showed that time-based subscriptions were hard to understand when everything was reduced to start and end date columns. The concept paired a timeline with an editable data view so users could work visually or numerically in the same flow.
We completed the reset and clickable concept in three days. The final walkthrough showed the full renewal flow, and internal leadership feedback identified the mockup as a leading contributor to the funding decision.
The story followed the renewal manager's work instead of the existing tool structure.
The concept gave leadership a specific product direction to assess.
The proposed workflow targeted shorter renewal processing and fewer pricing errors through automated calculations.
I used research and a working concept to help leadership decide whether a new product was worth funding. When the direction drifted from the evidence, I reset it before the review.
I used focused research to ground the concept quickly and keep the workflow tied to real problems.
I reset a direction that had become too constrained by the current platform and rebuilt it around the intended workflow.
The final concept made the opportunity clear enough for leadership to make a funding decision.
The concept showed what Workday could build, who it would help, and how the main renewal workflow could work.
This was concept-stage design work built around research, workflow definition, prototyping, and an executive funding review.
Customer interviews, workflow analysis, competitive research, stakeholder review
Figma, Photoshop, Illustrator; PHP/MySQL for interactive concept flows; executive presentation design
Scenario development, executive presentation flow, and funding story
Role: IC design lead. I owned the research, concept design, workflow, executive presentation, and product recommendation.
How I translated laser-operation knowledge into a stable preview system that preserves artwork, product geometry, orientation, and manufacturing constraints from design through approval.
A full-stack product design case study on keeping the saved design consistent across the editor, 3D preview, approval, and manufacturing handoff.
Customers had to approve a product they couldn't touch or inspect under different lighting. A flat proof could confirm spelling, but not orientation, side, material appearance, or protected hardware areas.
I framed the product requirements around five approval questions: Is the artwork the right size, on the correct side, upright, legible on this material, and clear of areas that can't be engraved?
If the preview changes between Studio and approval, the customer may approve something different from what they designed.
Wrong scale, side, rotation, or protected-region behavior can lead to wasted material, extra clarification, or a production error.
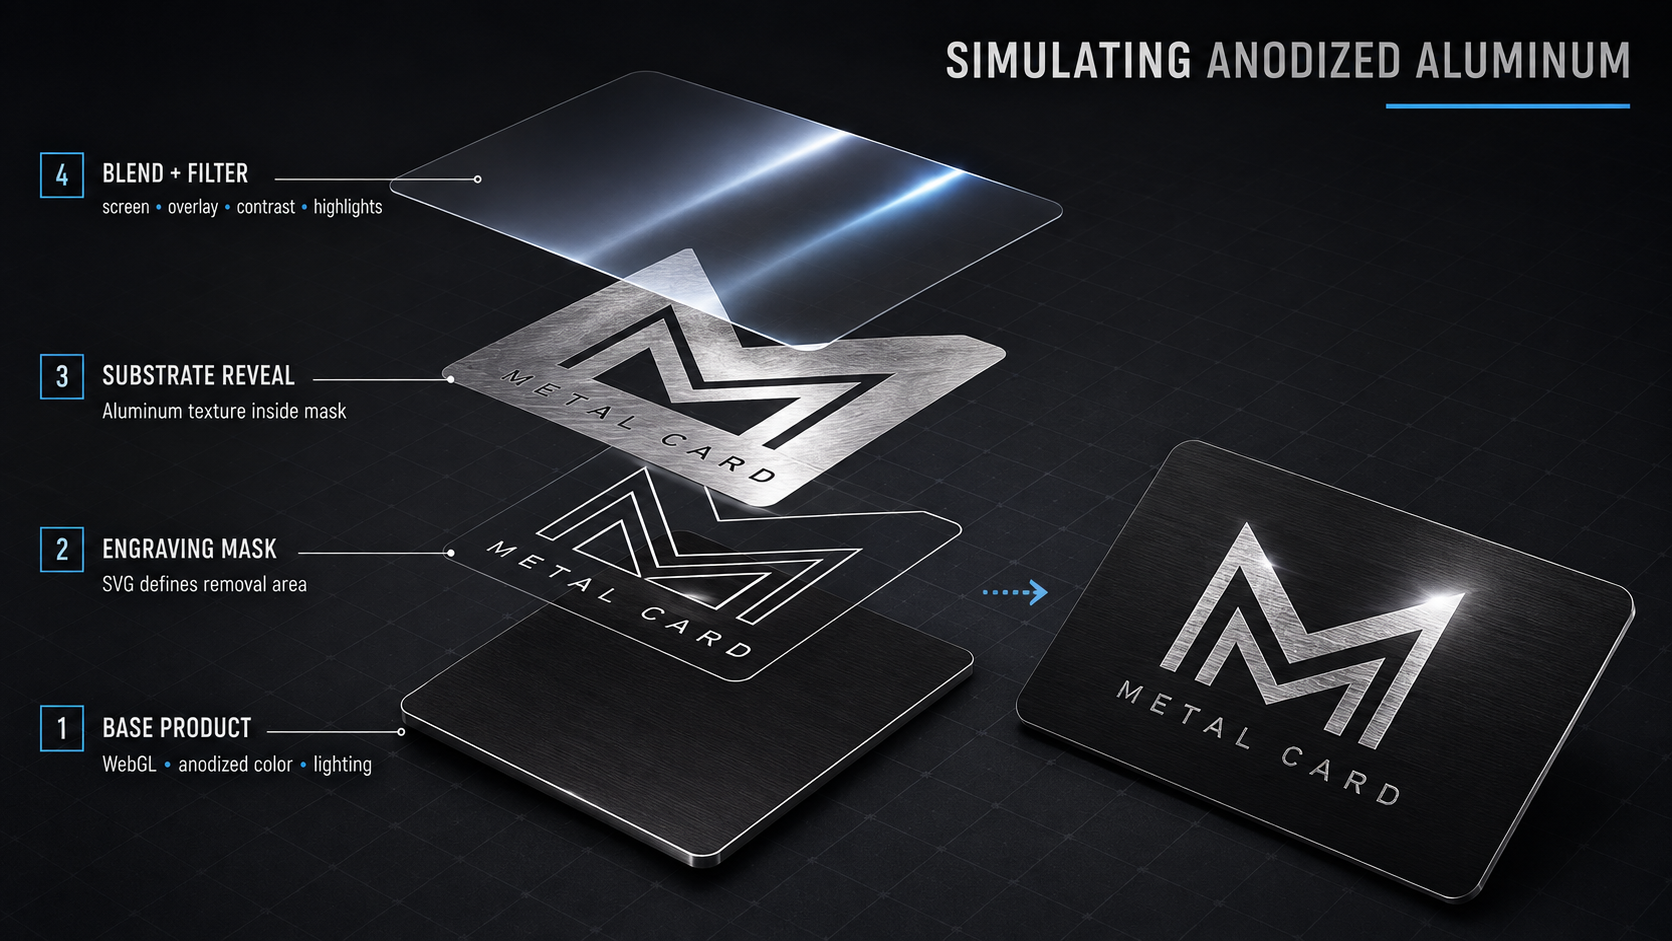
Keep the customer's design choices consistent everywhere they appear. The editor, saved draft, 3D preview, approval page, and production record use the same product ID, geometry, and transform rules.
Customers control placement, scale, crop, rotation, side, and relative appearance. Operators keep control of settings that depend on the machine, material, and physical testing.


Customers control what they can see and approve. Operators control the machine settings needed to reproduce it.
I turned laser-operation experience into interface and rendering rules. Variables that need physical testing stay in the operator workflow.
I map source luminance to relative engraving opacity and preserve contrast, exposure, crop, inversion, transparency, and text shade in the saved design. The preview shows relative tone. It doesn't claim that a gray value maps to a fixed laser setting.
The bugs looked different, but they came from the same missing rules. I traced each failure across Studio, saved drafts, and approval, then replaced one-off fixes with shared rules.
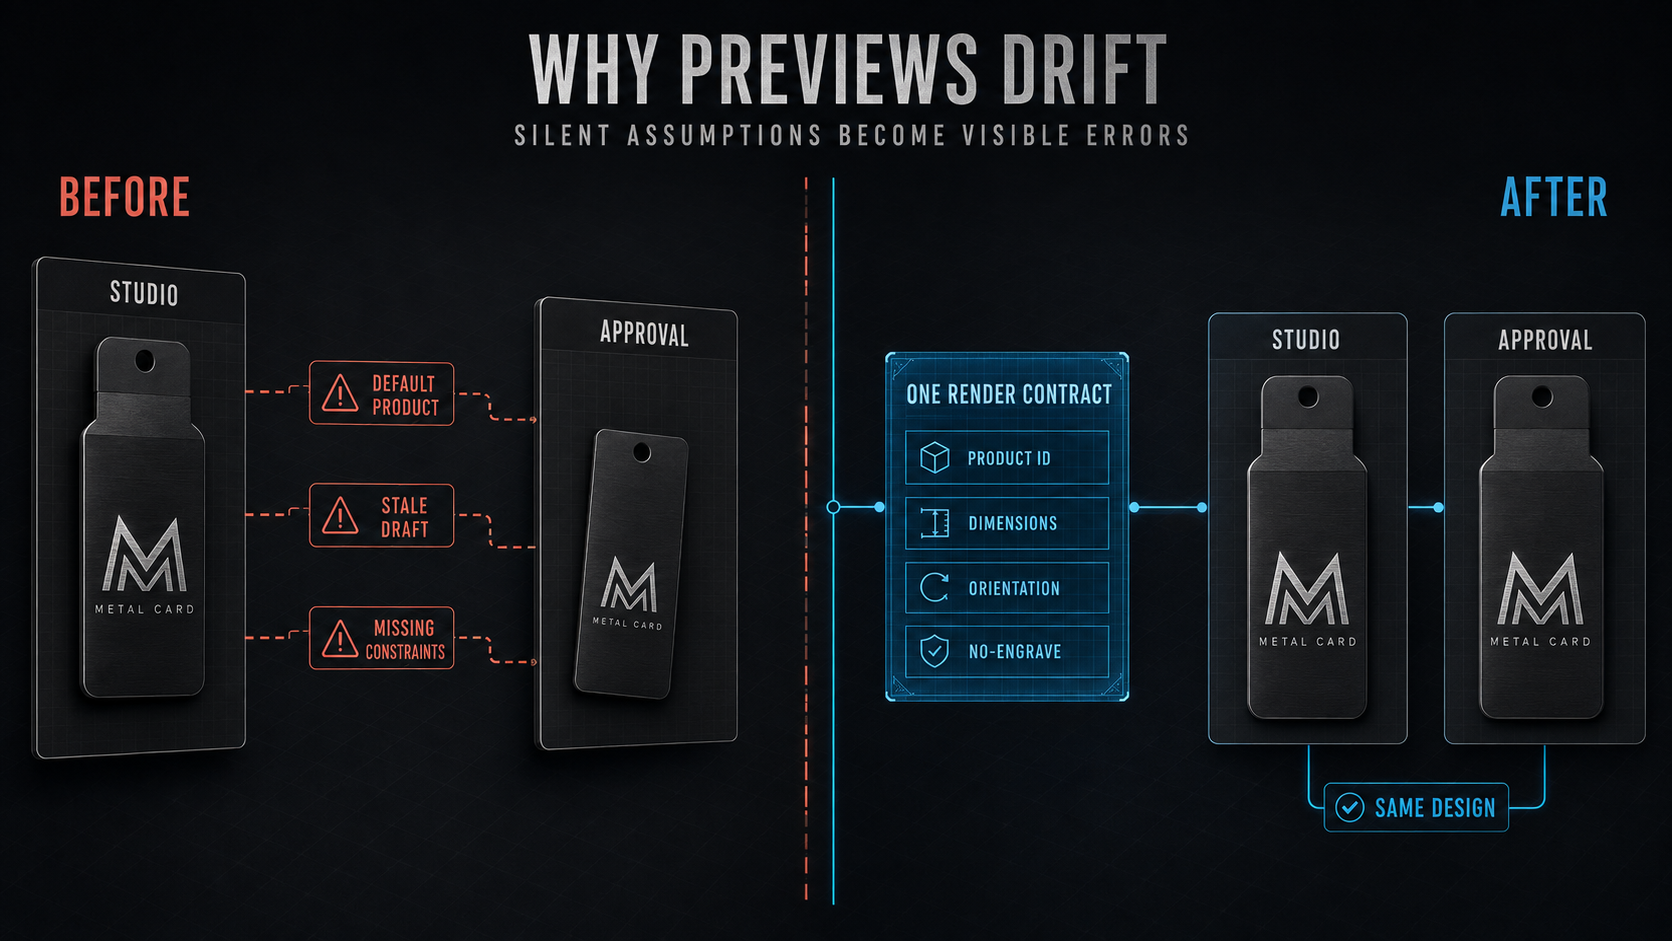
A luggage-tag design could appear correctly in Studio but shrink or inherit business-card dimensions in approval.
Each module was rebuilding product identity, dimensions, and rendering behavior from its own defaults.
I defined a versioned saved design format with the product ID, exact geometry, side state, transforms, and constraints. Studio and approval use that same data and the same layer renderer.
Studio and approval now reproduce the same saved design. Missing product data produces an error instead of a believable fallback.
Scale, crop, rotation, and back-side orientation could change as artwork moved between Canvas, SVG, and Three.js.
I traced rotation and mirroring across each boundary and found that more than one layer was changing the same artwork.
Textures stay in native coordinates. Mirroring happens in display space. Coordinate conversion happens only at named boundaries, and the completed 3D product rotates once.
Artwork retains its placement and readable orientation across sides, product proportions, and display rotations.
Protected regions could disappear after saving, while approval could open before the latest edits reached the draft.
The problem came from temporary browser geometry and navigation that could move ahead before the latest save finished.
I save protected-region geometry as SVG data and rebuild it downstream. Add to Cart now waits for a validated save before opening the approval draft.
Approval opens the latest committed design with its manufacturing constraints intact.
The saved design is the source of truth. Product geometry, side-specific state, transforms, and manufacturing constraints travel together from Studio through approval.

Product ID, exact dimensions, viewBox, side state, display rotation, layer transforms, material choices, and protected-region geometry.
Studio and approval use the same layer composition rules instead of independently rebuilding crop, tone, text, and image placement.
Missing or invalid product data blocks approval instead of silently using business-card dimensions.
Cards, luggage tags, and charms use the same editing, saving, texture, and approval flow. Each product provides its own SVG shape, dimensions, sides, materials, and protected regions.
Every template uses the same transform rules, front/back behavior, texture generation, approval flow, and rendering lifecycle.
SVG silhouette and holes, physical dimensions, viewBox, display rotation, sides, material options, and optional no-engrave geometry.
Canvas composition, contract validation, coordinate conversion, 3D extrusion, material rendering, interaction, saving, approval, and cleanup.
Adding a product means defining its template and settings instead of building a new renderer. The same rules that fixed luggage-tag drift also prevent old business-card defaults from leaking into new products.
The key decisions were where transforms happen, how physical constraints are saved, and when the renderer should run.
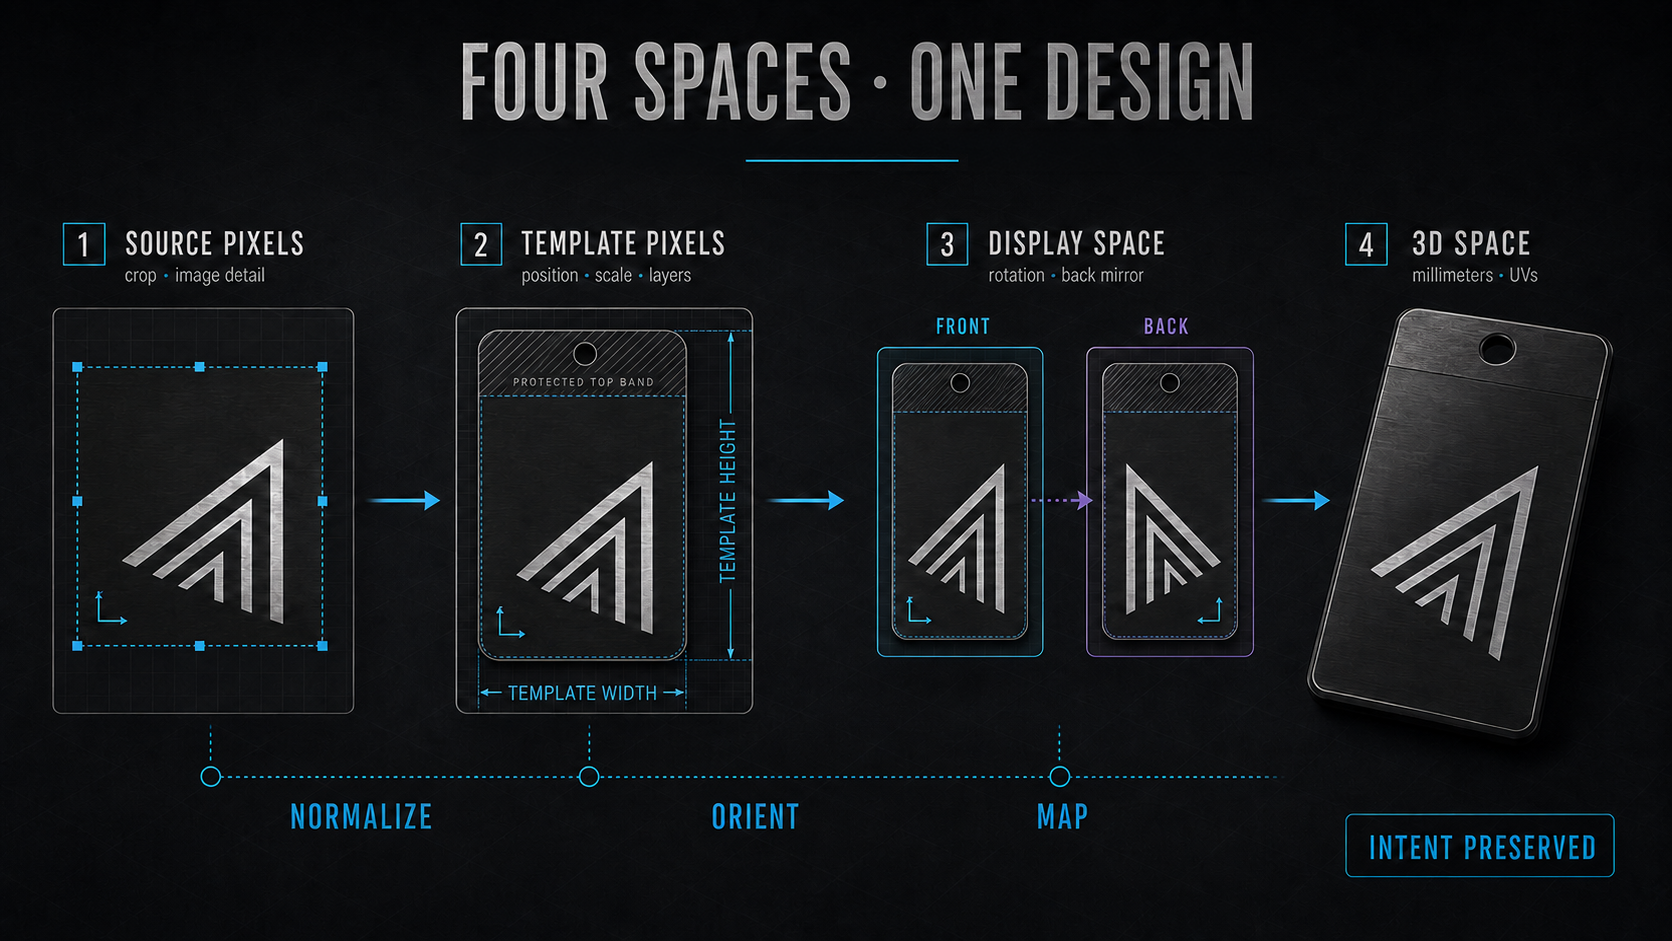
I documented the source, template, display, and Three.js spaces, then assigned rotation and mirroring to named boundaries. This kept front/back artwork readable without stretching the texture.
I represented holes and keep-out zones as serializable SVG geometry. The same shape suppresses engraving in Studio, the saved draft, approval, and downstream output.
A save waits until template geometry is ready. Textures initialize once. WebGL renders on demand, and the modal removes its observers on close. High-DPI devices only do the work needed for the current interaction.
Validation runs when state moves between the template, saved draft, approval, and device. It blocks incomplete data before it can create a convincing but wrong preview.
| BOUNDARY | IMPLEMENTED GUARD | USER-FACING BEHAVIOR |
|---|---|---|
| Template → draft | The saved design requires stable product IDs and exact side dimensions. | Approval can't silently inherit business-card dimensions. |
| Draft → approval | Add to Cart awaits the draft save and resolves the draft ID after persistence succeeds. | Approval opens from the latest committed design. |
| SVG → saved contract | Saving serializes SVG primitives and viewBoxes; approval rebuilds them. | Protected regions remain visible and unengraved across modules. |
| Studio → approval | Studio and approval use the same layer rules and versioned saved design format. | Crop, scale, rotation, side, and tonal adjustments remain consistent. |
| Modal → device | Textures initialize once, frames render on demand, and the modal disposes of renderers and observers. | The preview remains responsive on high-DPI and slower devices. |
Studio and approval now use the same saved design rules. Customer choices, product geometry, and production constraints stay connected through approval.
A consistent approval view for placement, orientation, relative contrast, and protected regions.
A saved design that carries the product geometry and constraints needed to interpret the order consistently.
Stable IDs, versioned geometry, defined transform rules, and errors that show missing data instead of hiding it.
A reusable template system for adding products without rebuilding dimensions, side behavior, or preview synchronization each time.
I connected the customer workflow to the saved design data, renderer, error states, performance behavior, and manufacturing handoff.
Defined which decisions customers could evaluate, which remained operator-owned, and what the preview needed to communicate before approval.
Defined the versioned saved design format, product template rules, coordinate boundaries, side behavior, protected-region geometry, and error states.
Implemented Canvas composition, SVG masking, Three.js materials, UV orientation, persistence sequencing, validation, and renderer cleanup.
Tested the same drafts across products, sides, Studio, and approval, then traced mismatches back through saved state and rendering boundaries.
Studio and approval use the same rules. New templates inherit those rules, customer choices stay consistent, and production constraints remain part of the saved design.
I built the rendering system myself so I could test geometry, orientation, saved state, and manufacturing constraints directly.
Figma, Photoshop, Illustrator; SVG editing for artwork preparation and masking logic; PHP/MySQL for interactive mockups
Three.js, JavaScript, Canvas API, SVG manipulation, PHP/MySQL for persistence, custom UV mapping
Cross-product testing, manufacturing constraint verification, operator review of production outputs
Role: Solo IC. I owned the UX, 3D rendering system, geometry and orientation rules, saved state, and production validation.
How I use AI to reduce mechanical overhead while strengthening design judgment, technical understanding, focus, and quality discipline.
How I use AI for drafting and repetitive work, automate checks where I can, and keep product decisions and final review with me.
AI could draft work quickly, but vague instructions led to invented details, repeated mistakes, and code that looked finished before I'd checked it against the product.
I use AI as one step in the workflow. I define what AI can draft, what the system can check automatically, and what I need to review myself.
If the request didn't define APIs, states, or interaction rules, the output filled in the gaps.
Fixing only the generated code didn't improve the original instructions, so the same mistake could return later.
Code that looked right could still fail accessibility, security, business rules, or the intended interaction.
Each step has a clear owner. The spec defines the work. AI drafts it. Automated checks catch errors the system can find. I review the product and release decisions.
Working rule: AI can reduce repetitive work, but I still need to understand and review anything that affects the user experience or reaches production.
Define behavior, states, expected data, design tokens, accessibility, and edge cases before AI starts.
Draft code, documentation, tests, or a first pass at organizing research from the spec.
Run syntax, linting, accessibility, integration, and security checks.
Review UX, business rules, technical decisions, edge cases, and release risk.
Commit the checked result. If the design changed, update the spec too.
If review finds a gap, I update the specification first so the next pass starts from the corrected rule.
The Markdown spec defines component behavior, states, expected data, accessibility requirements, design tokens, and examples. I use the same spec for implementation, review, and documentation.
Syntax checks, linters, audits, and integration tests catch errors the system can test before I review the work.
I review UX, security-sensitive behavior, research findings, business rules, technical decisions, and final approval.
Each failure added a rule, check, or spec so the same problem would be harder to repeat.
A generated component could look complete while inventing props, skipping states, or applying patterns inconsistently.
I was correcting the output, but the original instruction was still ambiguous.
I moved component behavior, states, accessibility, tokens, and edge cases into reusable Markdown specifications.
The fix became a rule that later components could reuse.
An AI-assisted bulk edit across more than 25 PHP files broke the syntax in multiple places.
The edit was fast, but I still had to remember to check every changed file.
I added a post-edit hook that runs php -l automatically on modified PHP files and blocks syntax errors from progressing.
That check became a required part of the workflow.
AI could find repeated themes, but it couldn't know what they meant in the context of the event, the user, or the product.
Finding repeated themes and deciding what they meant were two different tasks.
I used AI to transcribe and group responses. I corrected the transcripts, reviewed the groups, defined the personas, and decided what mattered for the product.
AI sped up the first pass, but the interview checks and the decisions that followed stayed with me.
For KPop-Swag.com, I conducted more than 20 interviews with fans and operators at live K-pop events. AI helped transcribe the interviews, group similar responses, and find repeated themes. I reviewed the results and decided what the findings meant for the product.
I planned and conducted the interviews, followed up on unexpected answers, and recorded the context around each response.
AI helped transcribe the interviews, group similar responses, find repeated themes, and draft the first version of the personas.
I corrected the transcripts, checked the themes against the interviews, defined the personas, and used the findings to make product decisions.
The research produced four working personas: fan, laser operator, staff administrator, and superadministrator. I used them to separate the customer, production, and administrative parts of the product.
I built more than 50 components during an eight-week product cycle. Each component started with a written spec that defined the behavior before I moved into implementation, checks, and documentation.
The spec defines saving, saved, connection failure, and storage-full states before I add the visual treatment.
AI helped draft the module and documentation. I defined the messages, timing, what happens when saving fails, where the work is saved, and the accessibility behavior.
Once the rules were written down, later components could reuse the same states, design tokens, accessibility requirements, and documentation structure. AI could move faster because the expected behavior was already clear.
Automated checks handle rules the system can test. I review anything that needs product judgment or affects release.
| Stage | Automated check | What I review |
|---|---|---|
| Generated code → review | Syntax checks, linting, formatting, and static analysis. | Does the implementation match the intended interaction, and can I maintain it? |
| Component → interface | ARIA checks, keyboard paths, focus behavior, states, and design token checks. | If something fails, does the user know what happened and what to do next? |
| Integration → application | Request and response behavior, database behavior, authentication, and dependency checks. | Does the integration follow the product rules, permissions, and recovery behavior? |
| Application → production | Regression tests, security review, and explicit approval before commit or release. | Do I understand the remaining risk, and is it acceptable for release? |
I use AI for repetitive work that's easy to check. I review product decisions, UX, security, research findings, and anything that affects release.
I don't ship generated work I can't explain, maintain, or check against the product requirements.
Writing the rule first forces me to make states, constraints, and edge cases explicit. Reviewing alternatives helps me catch gaps earlier.
I use the saved time for research, edge cases, interaction refinement, accessibility, and testing.
I used this workflow while taking KPop-Swag.com from concept to production as a solo full-stack designer and developer.
Written specs, component patterns, and automated checks reduced repeated explanation and carried corrections into later work.
AI handled work I could check. I reviewed the product decisions, research findings, technical decisions, risk, and final release.
I designed the workflow, wrote the specifications, made the product decisions, reviewed generated output in the running product, and owned the final release.
I defined what AI could draft, what the system could check automatically, and what I needed to review myself.
I wrote the component behavior, interaction states, expected data, accessibility requirements, design tokens, and edge-case rules.
I connected the specs to generation, automated checks, post-edit hooks, integration testing, documentation, and release checks.
I reviewed generated work in the running product, fixed UX and technical issues, and updated the source specs so the correction would carry forward.
AI became one tool in the product workflow. It reduced repetitive work while I still reviewed the customer experience, technical quality, and release risk.
I used the same tools I already relied on for design, development, testing, and documentation. AI helped draft and check work, while I kept the product decisions and final review.
Figma, Photoshop, Illustrator; PHP/MySQL for interactive mockups; AI to help organize and clean up handwritten specifications into Markdown.
PHP, MySQL, JavaScript; Codex for coding and QA; linting, automated tests, manual UX review, and integration testing.
Written specs, human review points, automated checks, and a feedback loop that puts corrections back into the source spec.
Role: Solo IC. I designed the AI-assisted workflow, made the product and design decisions, set the checks, and reviewed the output before release.
Designed a machine-aware settings and verification product that helps laser users find credible starting points, preserve context, and turn successful tests into reusable community knowledge.
A community-driven settings and verification product for real laser workflows
LaserMark DB helps people find and verify laser settings that match the machine, material, and result they are working with. It starts with a practical question: What's a credible starting point for this machine, this material, and this result?
I created LaserMark DB as a self-directed product. I own the design, product requirements, priorities, and prototype/build decisions. The product is preparing for beta with machine-aware search, settings detail, photo verification, project repositories, Q&A, moderation, and export support.
I owned the research, product definition, UX, requirements, information structure, priorities, and prototype/build. I also used my own experience with fiber and CO2 lasers to identify where the workflow breaks down in real use.
Defined the interaction model for settings discovery, evaluation, verification, and moderation.
Defined feature scope, workflow priorities, and the rules for evidence, review, and verification.
Built working prototypes to test ideas and tighten the requirements as the workflows came together.
I used the same approach throughout. I turned unclear workflows into specific product rules, tested those rules in the prototype, and revised them as the evidence changed.
Laser settings change with the machine, lens, material, thickness, finish, and intended result. People often piece together advice from scattered files, old manuals, forums, and trial and error.
Because the result is physical, a bad recommendation can waste material, cost shop time, or create a safety problem.
Users piece together settings from social groups, software forums, support docs, and personal notes.
A setting that worked once may not translate cleanly across a different machine, material finish, or lens setup.
Trial and error is expensive when the output is physical and the material may be hard to replace.
I used community research and direct laser experience to guide the product. Sources included Facebook chat interviews and group discussions, manufacturer support boards, Reddit, laser software forums, and my own work with fiber and CO2 lasers.
AI helped me organize notes, group repeated pain points, and find patterns across sources. I reviewed the source material myself and decided what was credible, what needed more validation, and what should affect the product.
Hands-on experience with fiber and CO2 lasers helped me separate plausible-looking advice from settings that were actually usable in a shop workflow.
It helped organize messy research notes without treating generated summaries as evidence.
The same themes kept showing up across community research, support discussions, manufacturer content, and my own laser use. AI helped group the input. I decided what the patterns meant and how the product should respond.
Users could often find settings, but not enough context to know whether those settings applied to their exact machine, material, finish, or intended result. That led me to treat trust as a workflow problem.
People were copying product details by hand from disconnected resources, guessing which fields mattered, and normalizing inconsistent parameters manually. That pattern directly led to the material prefill feature.
Variant URLs, product names, and material descriptions were often inconsistent. LaserMark DB keeps the source value, stores a normalized value when possible, and shows warnings when the match is uncertain.
Users wanted fast answers, but some materials and settings require caution. That pushed me toward reviewable outputs, visible warnings, and nulls when the evidence was weak.
People didn't only need answers. They needed a way to compare past jobs, reuse successful setups, and understand what changed. That influenced the data model and the decision to keep machine, material, result, and evidence connected.
Forums and groups were useful for language and pain points, but it was often hard to tell why a setting should be trusted. That reinforced the need for verification, source attribution, version history, and moderation.
LaserMark DB should reduce setup work while keeping uncertainty visible. The workflow is built around search, context, evidence, review, and clear handling of unknown values.
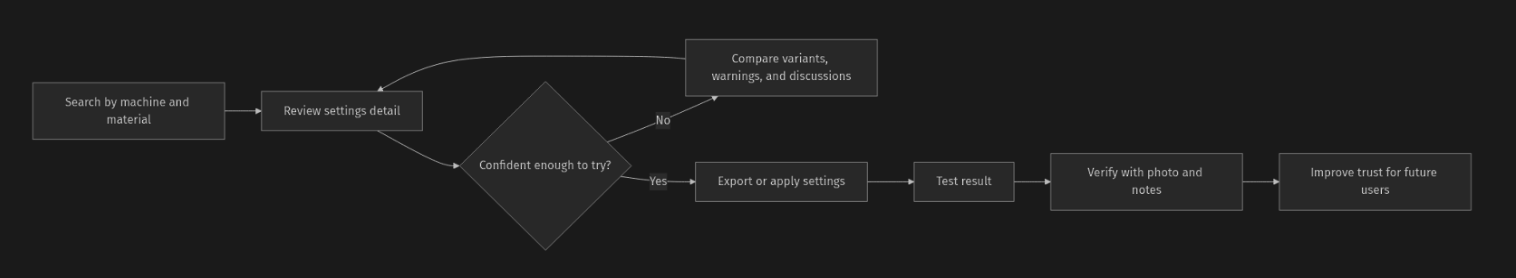
Search by machine, material, or keyword, then narrow with filters and visible trust cues.
Review parameters, author context, verification counts, warnings, and linked discussions before applying a setting.
Export settings to the tools people already use, including LightBurn-compatible formats and standard data exports.
Turn a one-time result into reusable community knowledge through photos, notes, and visible validation.
Keep version history and discussion attached so the database can improve instead of freezing bad assumptions in place.
Use warnings, review, and moderation to add scrutiny to a setting before sharing it.
Material prefill came directly from a repeated problem in the research and my own use. People were copying product details from supplier pages before they could even start testing.
The rule was simple: automate what the page clearly provides, and leave uncertain fields for review.
A user pastes a public product URL. LaserMark DB tries to fill the image, product name, description, dimensions, material family, and related attributes.
It helps hobby users and shops reduce repetitive setup work, especially when they're testing new material sources or documenting a result for reuse.
It reduces manual entry without pretending the system knows more than it does. Review, evidence, and ambiguity remain visible parts of the experience.
LaserMark DB checks structured product markup first, then page metadata, visible content, URL signals, and site-specific rules. For each field, it keeps the source value, the normalized value, supporting evidence, warnings, and confidence so the user can review what was found.
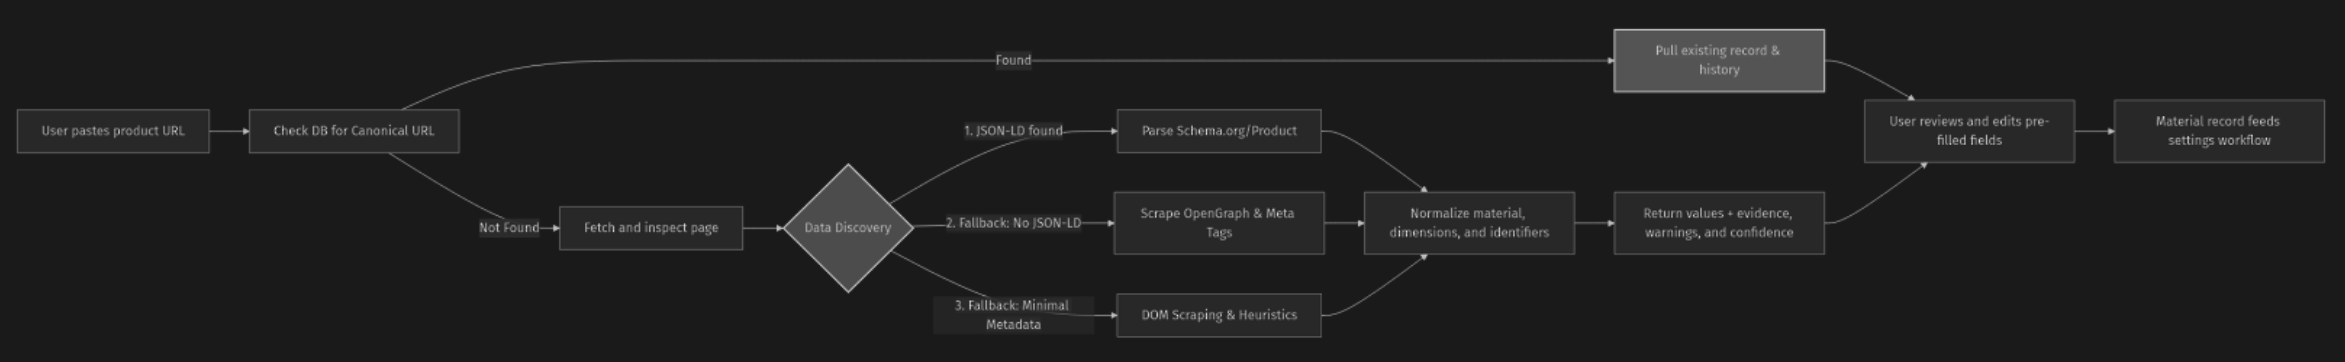
The harder cases are messy supplier names, machine variants, finishes, sizes, and material terms that don't line up cleanly. The rules define when to keep a variant, when to normalize a value, and when to leave a field unknown because the evidence is weak or conflicting.
Unknown values should stay unknown. Nulls are better than confident-looking guesses when the source data is weak.
Pre-fill should speed up setup, but the user should still understand what came from the source page and what needs judgment before reuse.
Users can test a setting, upload photos, rate the result, and add notes for the next person. The product should make it easy to add and review that evidence.
Photos and notes show what actually happened during the test.
Author identity, reputation, and version history help users see who shared the setting and how it changed.
Verification improves future confidence and helps the database evolve instead of remaining static.
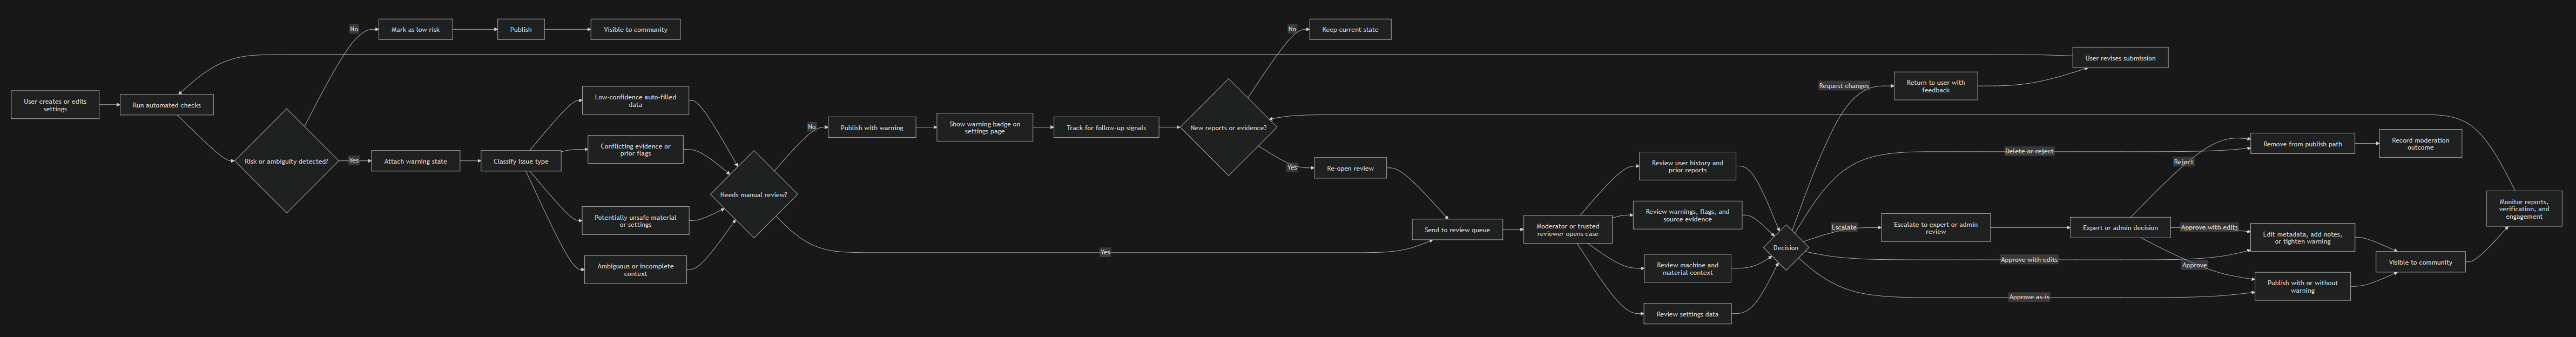
I turned a messy laser workflow into specific product rules using community research, direct laser experience, working prototypes, and AI-assisted note organization.
I connected search, settings, evidence, verification, reuse, and moderation into one workflow.
I reduced repetitive setup work while keeping source evidence, review, and uncertainty visible.
I used AI and lightweight development to move faster, while keeping design, priorities, validation, and final decisions with me.
The requirements make constraints, uncertainty, source evidence, and review responsibilities visible.
This was my second end-to-end solo product. AI helped organize domain notes and speed up implementation, while I owned the product rules and decisions.
Figma, Photoshop, Illustrator; PHP/MySQL for interactive mockups; custom design system, source evidence, and verification workflows
PHP, MySQL, JavaScript; Codex for coding and QA; AI to organize handwritten specs and domain notes into Markdown
Reddit community research, user surveys, and 15+ years of laser operation experience; AI helped organize notes and I reviewed the source material myself
Role: Solo IC. I wrote the specs from direct domain experience. AI helped organize notes and speed up development, and I reviewed the output.
Led the redesign of three enterprise planning models into one coherent interaction system, preserving expert speed while modernizing the platform foundation.
Rebuilding a core planning workspace so finance teams could stay in one system and work faster with clearer, more consistent behavior.
Adaptive Sheets is where planners and financial analysts build budgets, compare periods, review anomalies, and work through close. Over time, similar tasks started behaving differently across sheet types, which made the product harder to learn and slower to use.
The goal was to bring standard, modeled, and cube sheets into one interaction system while moving the product to HTML5 and JavaScript. I was the lead product designer and drove the interaction direction, design quality, and many of the product decisions that shipped.
Context menus hid actions, navigation changed from page to page, and similar tasks worked differently across sheet types. That slowed down high-attention planning work.
Cube sheets also depended on third-party Java applet technology that was being shut down. We had to replace that foundation while keeping daily planning work running.
Actions, menus, and navigation patterns shifted too much across contexts.
Java applet dependency and other aging platform choices forced deeper rework.
Many planners still fell back to Excel because the spreadsheet behavior felt faster and more familiar.
We started with the assumption that users preferred working in Excel and then moving data into Adaptive. This came up at Adaptive Live and in support cases. Customer research showed something different: people used Excel because parts of the planning workflow in Adaptive were harder than they needed to be.
Users wanted to stay in one workspace when it was faster and easier than switching tools.
Formatting mattered because it helped users read and check financial data. Totals, decimals, comparison, and layout structure had to stay clear under pressure.
Users wanted to do more inside Sheets instead of bouncing to Excel or separate reports.
Totals, variance, and layout cues helped users check data quickly.
Historical context inside the workflow helped users make better planning decisions.
Drag and drop, filters, and parameters needed visible cues that showed what would happen next.
Inline graphs added noise during planning and data-entry work.
Things like double lines above totals and direct formatting weren't cosmetic requests.
The design focused on speed, consistency, and confidence during planning work.
Designers, documentation, research, product, engineering, QA, and an agency partner all contributed. I led product design and kept the interaction system consistent as the work expanded.
I led interaction design, navigation, page structure, visual direction, and component behavior. I also worked with product and engineering leadership to turn research into roadmap decisions.
Research planning, engineering implementation, documentation, QA, and rollout were shared across the team.
I pushed to include accessibility in component and interaction requirements from the start. I also worked closely with engineering on the cube-sheet rebuild and its tradeoffs.
I kept decisions tied to user evidence, product constraints, and what the team could support well.
Standard, modeled, and cube sheets share many actions but have different data structures. The interaction system had to keep common behavior consistent while supporting those differences.
Classic budgets, forecasts, and financial statements where people review or enter values across time and organizational levels.
Object-based planning for people, projects, assets, and contracts where each row behaves more like a business object.
Multidimensional planning across things like product, customer, scenario, region, and time.
Shared actions stay familiar across sheet types. Specialized controls appear only where the underlying data model requires them.
We defined shared rules for moving, editing, formatting, comparing, and understanding state across all three sheet types.
We standardized toolbars, menus, side panels, formula workflows, and feedback states. Repeated actions needed to work the same way so users could stay fast during high-attention work.
Users no longer had to relearn where actions lived each time they changed context.
Formatting, entry, save behavior, and state cues became much more consistent.
We kept core actions easy to find without disrupting the muscle memory power users relied on.
Cube sheets depended on third-party technology that was being shut down. We had to rebuild the foundation and decide which legacy behaviors were required for launch and which could wait.
We explained those tradeoffs directly to customers and prioritized the features that most affected daily work and long-term stability.
We rebuilt the cube-sheet foundation first and delayed lower-priority legacy behavior.
We prioritized structure, formatting, and workflow clarity over theming and customization.
We moved inline graphs out of core entry workflows because they distracted from planning work.
Those choices helped us ship a more stable product without claiming support for features we hadn't rebuilt well yet.
I included accessibility requirements in components, visual rules, and interaction behavior from the start instead of leaving them for post-launch fixes.
The product became easier to use for a wider range of people, especially in keyboard-heavy workflows.
Accessibility improvements also supported federal RFQ requirements and customer evaluations.
Accessibility became a standard for new work.
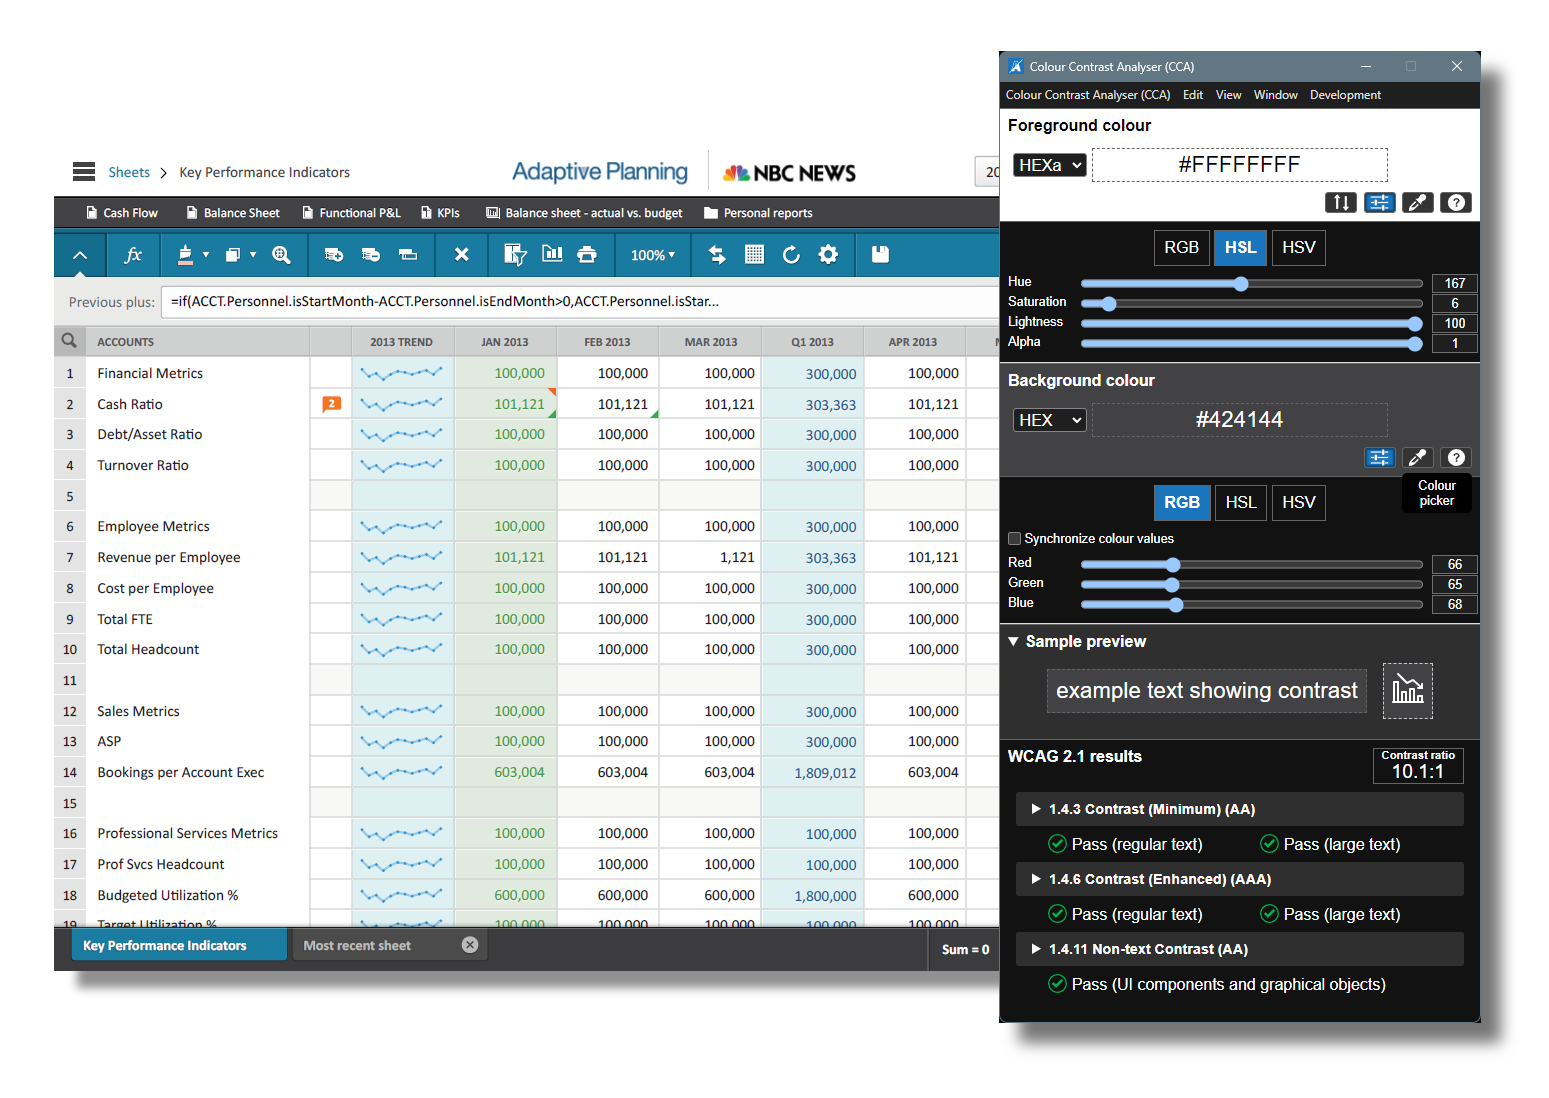
We clarified approvals, component documentation, and collaboration across design, engineering, and QA. Over time, design moved from just-in-time delivery to roughly two sprints ahead.
I coached junior designers on documenting work for engineers, spotting accessibility gaps, and presenting ideas more effectively.
Shared rules and better component documentation reduced ambiguity during implementation.
We added regular reviews for usability, accessibility, and tech debt so those issues were part of normal delivery.
The redesign shipped in eight months. Sheet-related support calls dropped, month-end close got faster for large customers, and the team improved its design and development rhythm.
"You've made me a better father and husband. I don't have to stay late anymore and I get to spend more time with my wife and kids!"
The comment put the metrics in practical terms: less stress and fewer late nights during critical planning work.
These research findings directly affected the design.
Daily readability and speed mattered more than one-time setup polish.
Many users still found direct formatting and familiar spreadsheet structure easier.
Small structural cues carried financial meaning and had to be preserved.
Visible drop targets and cues made the interaction easier to learn.
Users expected filters and parameters to be more directly editable.
Users cared more about formatting and workflow clarity than themes.
The work required close collaboration with engineering, accessibility specialists, product, research, QA, and documentation.
Figma, Photoshop, Illustrator; PHP/MySQL for interactive mockups; Workday's design system
Comparative usability studies, structured interviews with FP&A teams, accessibility validation (WCAG 2.0)
Direct partnership with engineering leads, accessibility team, and design system stakeholders throughout implementation
Role: IC design lead. I owned end-to-end interaction design, research synthesis, specifications, accessibility review, and design validation through release.
Used pattern design, dependency mapping, and a high-risk proof of concept to show that a proposed UI migration would not resolve the underlying platform problem.
Using a component redesign to test whether Workday should replace a larger business-process workflow
Task Wizard started as a redesign of a shallow, inflexible wizard used in complex Workday business processes. The goal was to support deeper processes, clearer navigation, better validation, and accessibility.
When we applied the pattern to a real, highly connected business process, the larger problem became clear. A new wizard could improve the UI, but platform limits, ownership, and dependencies across many product teams blocked the migration.
I led the design and research work. I turned findings into requirements, mapped cross-product dependencies, documented functional gaps, set scope with product management, and presented the recommendation to leadership.
Redesigned Task Wizard to support grouped steps, deeper hierarchies, clearer validation, accessibility, and more reliable navigation.
Worked across product areas to document business-process requirements, dependencies, and blockers to adoption.
Defined adoption scenarios and the final recommendation using UX evidence, engineering constraints, and cross-team readiness.
The component team had limited design capacity, so I owned the detailed states, edge cases, and engineering redlines while mentoring a peer on documentation. Workday didn't have an existing pattern that fit the Business Process Engine, so I designed a custom tree navigation model around its technical constraints.
For users, business processes were hard to navigate and too rigid for many company workflows. For product and engineering teams, the same processes were hard to scale and configure because of legacy code, security rules, and connected logic.
Processes were long, brittle, and hard to follow. Even experienced users had to work around the flow.
Legacy code, sequencing dependencies, and functional gaps made migration and support expensive.
Full adoption required long-term commitment from many product teams.
The more we traced the workflow, the clearer it became that a new wizard couldn't solve the platform problem on its own.
The original wizard supported one level and up to five steps. Research showed that was rarely enough. I designed grouped steps, progressive disclosure, non-linear navigation, explicit validation states, expand-and-collapse behavior, keyboard support, RTL support, and double-byte language handling.
Grouped steps showed the structure of a long process without forcing everything into one flat list.
The pattern explicitly defined validation, current step, saved return state, and expand or collapse behavior.
The pattern included keyboard navigation, color, localization, and accessibility requirements from the start.
I applied Task Wizard to Change Job, one of Workday's most complex business processes. If the pattern worked there, it could support broader adoption. If it failed, we would know where the larger limits were.
The proof of concept changed the recommendation. We identified more than 80 related business processes and many sequencing dependencies. The UX improvements worked, but full migration would require major platform work and long-term commitment across teams.
It tested the pattern against a real, highly connected process instead of a simplified sample.
Functional gaps, sequencing dependencies, unclear ownership, and the real cost of adoption.
The UI could improve navigation, but the platform constraints still needed separate work.
We presented three adoption scenarios and recommended stopping the replacement as scoped. Reaching parity would take multiple releases. A full transition would require retiring the existing process model, redirecting legacy development, and keeping many product teams committed for three to five years.
Security gaps, missing functionality, and legacy dependencies made the near-term migration too risky for the expected value.
Full adoption required sustained commitment from hundreds of process owners and product teams.
The research pointed toward a broader automation engine, visual process builder, task manager, and scheduler. None of that comes from a wizard redesign alone.
The work mapped the business-process flow, dependencies, and integration points in one place. It brought more than twenty product experts around the same constraints and gave leadership concrete options before committing to a costly migration. We didn't find a viable path for the proposed replacement, but the analysis showed what larger platform work the migration would need.
More than a year of research turned local complaints and assumptions into a shared view of the platform problem.
More than twenty product experts reviewed the same dependencies and agreed on the main blockers.
The discussion moved from what was broken to what platform work had to happen before a replacement was viable.
The design work helped leadership avoid committing to a migration before the platform was ready.
The work combined pattern analysis, dependency mapping, prototyping, and cross-product review.
Expert interviews, dependency mapping, workflow analysis, and pattern review across 20+ product areas
Figma, Photoshop, Illustrator; PHP/MySQL for interactive mockups; pattern libraries for validation
Cross-product dependency diagrams, requirement mapping, and recommendation decks
Role: IC design lead. I owned the research, dependency analysis, prototype, validation, and recommendation to leadership.
Evolved recall discovery from a rough proof of concept into a faster, more visual, trustworthy, and action-oriented consumer experience through research and testing.
Making recall search faster, more visual, and easier for consumers to act on
RecallSeeker is a five-person bootstrapped 0-to-1 startup. Most consumers don't monitor recall databases, and public recall tools are often slow, text-heavy, and hard to browse. The product needed to help people find the right product, understand the risk, and know what to do next.
This case study shows how the product changed from proof of concept to V1. The main questions were simple. Can users identify the right product quickly? Can they understand what matters? Can they act without having to decode the recall data first?
I was a founding designer working with a senior quant/data analyst, senior UX researcher, senior AI/ML engineer, and senior product manager. I used surveys, personas, process maps, low-fidelity concepts, A/B testing, and working screens to understand how people find and respond to recalls.
Created surveys, reviewed behavior patterns, and turned the findings into personas, journey maps, and product priorities.
Designed and compared dashboard, search, registration, and recall detail concepts across mockup, proof of concept, and V1 states.
Explored where AI could help while keeping approvals, verification, and status clear to users.
The interface focused on what users needed to recognize the product, understand the risk, and take the next step.
Recall information is often presented as dense text with inconsistent product names and little visual confirmation. That makes it harder for consumers to tell whether a recall applies to something they own.
The product had to make product matching, status, and next steps clear enough for users to act with confidence.
Many consumers are passive and only learn about recalls by chance, long after a better notification or registration system could have helped.
Text-heavy search and inconsistent naming make it harder to match the recall to the real product in a consumer's home.
If the system doesn't clearly show what's affected and what to do next, users hesitate, ignore the issue, or postpone action.
Busy consumers rarely monitor recall databases, so they often find safety information by chance.
Survey work, personas, process maps, and testing showed that most consumers were passive. They weren't regularly checking recalls or consistently registering products. Many learned about recalls through news, social media, or store notices.
49.6% of respondents were only somewhat aware of recalls, and 25.6% weren't aware at all.
Only 37.2% had ever acted on a recall. The product needed clearer product identification and simpler next steps.
Email was the most preferred notification channel, so it became the primary direction for proactive communication.

The product had to connect product registration, recall detection, communication, and resolution without making users manage the complexity behind those steps.
The first dashboard focused on watchlists, overview metrics, and a brand safety monitor. Testing showed that users mainly wanted to know whether they owned a recalled product and what they should do next.
The POC and V1 moved toward product registration, clearer status groups, stronger default filters, tighter layouts, and more emphasis on products with active recalls.
Products with active recalls get stronger visual priority than safe products or general monitoring metrics.
Mixed views of safe and recalled products diluted attention and made it harder to see what needed action.
Users wanted a way to run a recall check immediately instead of waiting for nightly matching.
Search moved from dense recall text toward image-led results, clearer titles, and simpler actions. Users cared more about recognizing the product than reading a recall reference number.
Keyword search was weak when users didn't know the exact product name. Semantic search handled those cases better. In the deck example, searching for Elmo Nightlight returned the correct recall first, while a comparable public search experience buried the answer several pages deep and loaded more slowly.
Images, mini carousels, and stronger cards helped users identify relevant products faster than text-only results.
Intent-aware search handled naming differences and misspellings better than exact keyword logic.
Consistent actions for sharing, bookmarking, and quick access made results easier to scan.
The detail page puts the practical questions first. What product is affected? Why does it matter? What should I do now? Stronger grouping, better images, clearer contact information, and accessible controls support those answers.
The detail experience included keyboard navigation, accessible image handling, and predictable lightbox behavior from the start.
While exploring AI-assisted recall processing, important steps still needed clear verification and a way to correct problems. That led to more explicit confirmation around product registration, address details, resolution status, and outbound messages.
Users wanted recall status and blockers shown closer to the product card.
Confirming address, product details, or resolution status gives users a chance to catch mistakes before the workflow continues.
When a case needs human review, the system shows who needs to verify it and what is blocking progress.
The product connects search with the follow-up work needed to resolve the recall.
The product became more visual, accessible, and action-oriented. Search and navigation got faster, and users could identify recalled products more quickly in testing.
Average page navigation performance improved by more than 90% compared with a public benchmark experience cited in the deck.
Visual product cards improved recall identification speed by 60 to 80% in a small A/B test.
The product met WCAG AA targets while improving clarity, hierarchy, and richer metadata handling.
I used research, testing, and product structure to turn dense recall data into a clearer path from product recognition to action.
I used surveys, personas, process maps, and testing to keep decisions tied to observed behavior.
I prioritized product recognition, clear status, and obvious next steps.
I designed the consumer experience and the supporting verification workflow together.
RecallSeeker helps people notice a relevant recall, understand it, and take action.
AI helped organize research notes and specifications. I owned the research interpretation and design decisions.
Figma, Photoshop, Illustrator; PHP/MySQL for interactive mockups; validated all AI outputs for accuracy
User surveys, persona development, process mapping, usability testing; AI to organize and polish my notes into specs; WCAG 2.1 AA validation
Codex for coding and QA; I created the component specs and design system documentation, with AI helping organize the material
Role: IC product designer. I owned the research, design decisions, and specifications. AI helped organize notes and speed up prototyping, and I reviewed the output.
Designed a bounded multi-agent operating model that adds safe automation, auditability, and explicit human approval to a compliant recall workflow.
A bounded AI agent workflow for recall operations, with clear roles, human approval, and a complete audit trail.
Recall teams have to detect a possible hazard, verify the facts, handle regulatory requirements, notify customers, track the remedy, and keep a complete record. Those steps often happen across separate tools and manual handoffs.
For RecallSeeker, I defined where AI agents could help inside that workflow. Each agent has a narrow job, uses approved tools and data, and stops for human review when the decision carries more risk.

I defined where agents could act in recall management, what tools and data they could use, when they had to stop, what they had to record, and which steps required human approval.
Mapped the recall workflow from incident detection through closure and identified where automation could reduce manual coordination without taking control away from operators.
Defined each agent's job, inputs, outputs, handoffs, and failure states.
Defined how agent changes would be tested, what data agents could use, and which actions required approval.
I worked alongside an ML engineer, an AI architect, a product manager, and a researcher. My architect and I worked through where live LLM access was actually worth its cost and latency, since routing every request through the model would have been the simplest path to build but not the cheapest or fastest one to run. We settled on a fast keyword path for common requests, with only ambiguous ones falling back to the connected model, and I built the copilot's intent-recognition flow around that split.
The UX includes the rules behind the interface. It defines what the system may do, what it must explain, and when it must stop for a person.
Detection, compliance, communication, product recovery, and closure each have different rules, owners, and evidence requirements. When those steps live in separate systems, teams lose time figuring out what happened, what is blocked, and what should happen next.
Automation needs clear limits, supporting evidence, and a complete log. Key decisions also need an explicit owner.
Teams coordinate intake, compliance, customer outreach, and remediation across separate workflows that don't naturally stay in sync.
Mistakes in messaging, regulatory reporting, or product recovery can create legal, operational, and safety consequences.
Without a shared system of record, it's difficult to know what happened, what is blocked, and whether closure requirements are truly complete.
Before I designed the role model or the guardrails, I talked with practitioners across the functions a recall actually touches, risk management, manufacturing and quality, retail and logistics including last-mile delivery, reporting analysts, and legal and regulatory compliance. Their day-to-day problems, not a feature wishlist, are what most of the earlier decisions in this case study respond to.
Risk teams described piecing together a possible hazard from customer complaints, retailer returns, and safety-database reports that live in separate systems, so an early pattern gets missed until enough of it has already happened. Detect and the shared telemetry layer exist to correlate those reports in one place instead of after the fact.
Manufacturing and quality teams said the slowest part of a recall is rarely the decision, it's reconciling which lots, suppliers, and distribution channels are actually affected across systems that were never built to talk to each other. The compile-SKU-list and risk-assessment agent types exist because that reconciliation is exactly the kind of narrow, evidence-bound task an agent can accelerate without taking the call itself.
Retail contacts described recall notices arriving as a static document they then had to manually match against their own inventory, so shelf pulls lag the manufacturer's own timeline by days. This concept doesn't solve retail-side inventory matching directly, but the structured recall record it keeps is what a retailer integration would eventually read instead of a PDF.
Logistics and last-mile contacts said returns, replacements, and proof of destruction for a recall are usually handled with the same ad hoc tools as a normal return, even though a recall needs its own chain of custody. Resolve and the product recovery tracking tool exist to give that work a defined owner and a defined record instead of a workaround.
Analysts said the status of an active recall usually lives in a spreadsheet someone updates by hand, so a leadership or regulator update means stopping to reconstruct what already happened. The real-time dashboard and the analytics tool pull from the same event stream every role already writes to, so that reconstruction stops being necessary.
Legal and compliance contacts were the most direct about this, in a dispute or an audit the record of who decided what, and on which regulation, is usually scattered across email and meeting notes. The audit trail, the required approval notes, and the citation the regulatory agent returns exist because that record has to survive scrutiny after the fact, not just make sense in the moment.
The core recall workflow has to work without AI. Incident intake, regulatory steps, customer notifications, recovery tracking, and audit logs stand on their own. Agents can then help guide, recommend, draft, validate, and coordinate specific steps.
The workflow still works without agents, so the product doesn't depend on AI to complete a recall.
Each agent owns a narrow part of the process. That reduces overlap and limits how far a bad output can spread.
Agents use tools with defined actions and states. New tools can be added without changing every agent.
The result is a workflow where AI can help without removing human ownership.
The workflow follows the recall itself. Detect finds and structures a possible incident. Validate checks the evidence and risk. Comms handles outreach and acknowledgements. Resolve tracks returns, replacements, or destruction. Audit records the full chain.
Each role uses task-specific tools plus shared services for event tracking, coordination, analytics, and recorded decisions. Operators can still see what the system did and why.
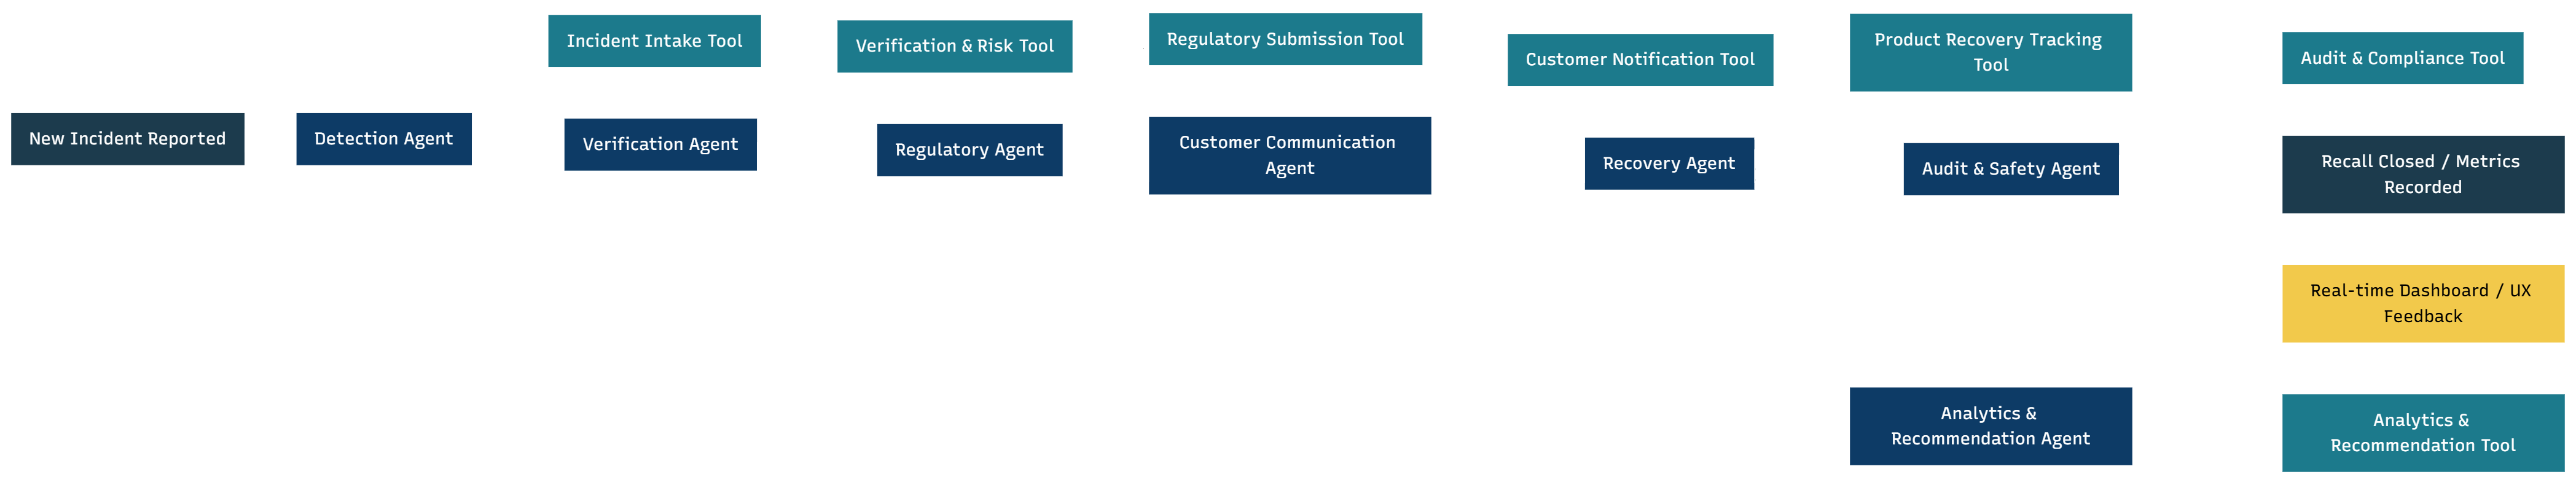
Each handoff shows the current stage, the recommendation, the supporting evidence, and the next action.
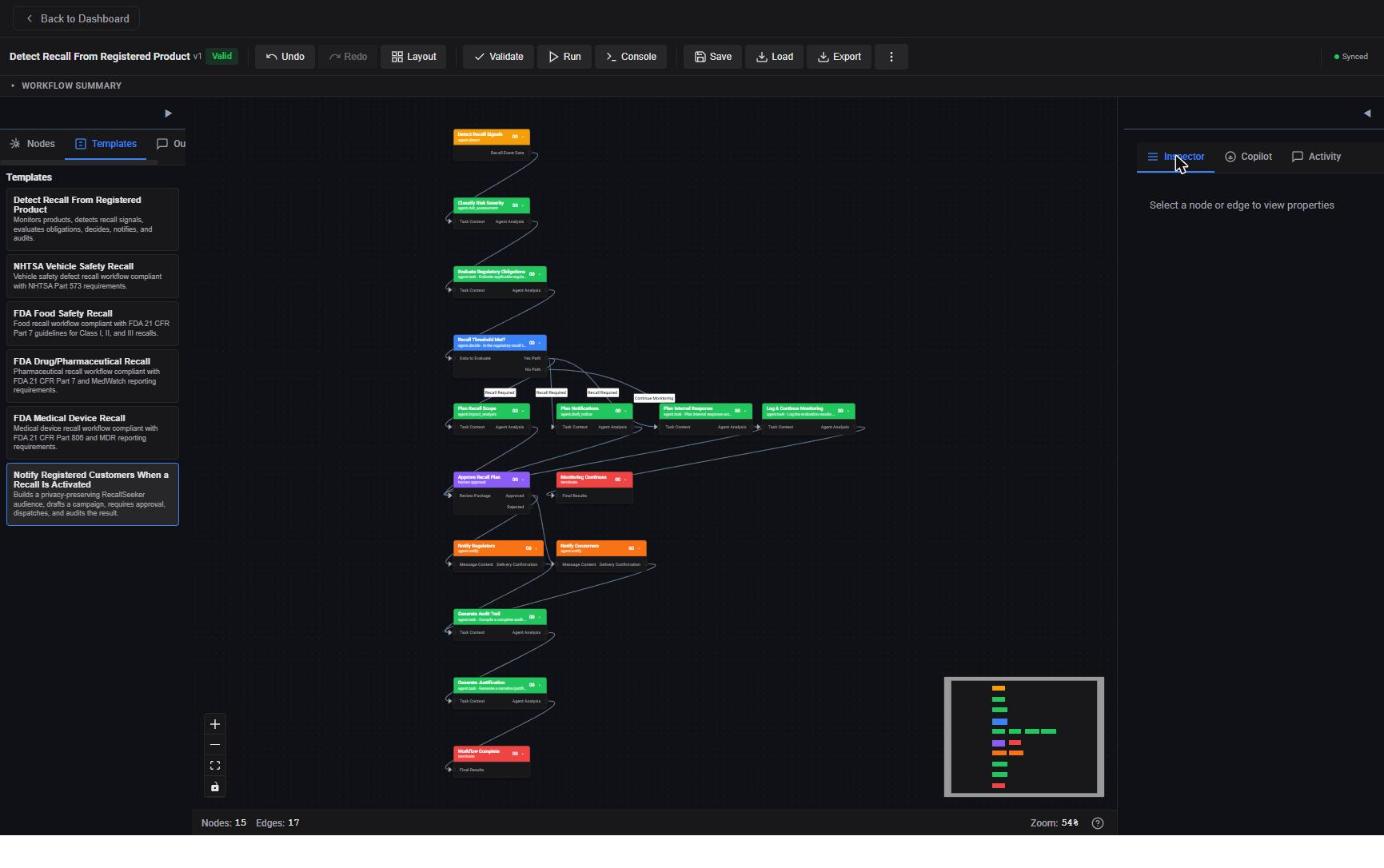
The graph runs on seven governed node types: a recall trigger, decision gates, agent tasks, approval gates, external-system calls, notifications, and a termination state. Every workflow is built from that same small set, simple or complex.
Each role states what it owns, what it won't do, and what happens when the evidence is incomplete.
Underneath those five roles sits a library of fifteen task-specific agent types: plan, research, build, draft notice, compile SKU list, generate filing, risk assessment, impact analysis, customer outreach, compliance check, and more. A workflow author picks the narrowest tool for each step instead of asking one generalist agent to do everything.
Narrow roles reduce overlap and make handoffs easier for users and internal teams to follow.
Users can see why an agent acted because each role is tied to a specific job.
When every role has a narrow purpose, it becomes clearer what should be passed forward, what should be rejected, and what should be escalated.
Each role also keeps one task-specific tool of its own, detect has an intake tool, comms has a notification tool, and so on, but event tracking, workflow coordination, analytics, and the recorded-decisions log aren't owned by any single role. All five draw from that same shared layer instead of keeping separate copies, so a dashboard built on top of it reflects the whole recall in progress, not just whatever one agent happened to log.
Regulatory citation doesn't sit inside every agent's own prompt. Validate and Audit are the two roles that actually need to ground a decision in a specific standard, so both call a dedicated regulatory agent instead of relying on whatever the underlying model remembers. That agent runs its own retrieval against a knowledge graph of recall regulations, not a single flat lookup, because tracing which section supersedes which, or which rule applies to a given product category, takes more than one search. The citation it returns is what shows up in the audit trail and in the approval screen.
The six shipped templates cover the common recall paths, but no two businesses run a recall exactly the same way. A manufacturer with three product lines and a distributor coordinating a dozen retailers need different versions of the same workflow, and forcing every business into one fixed template works against the whole point of moving to a single source of truth. Letting a team adjust or build the workflow that actually fits how they operate is what makes a recall system worth switching to, instead of one more rigid system to work around.
Instead of dragging every node by hand, an operator can describe what they want: "add an approval gate node," "connect these nodes," "explain this workflow." The copilot reads the request and responds. If the request changes the graph, it proposes an edit and waits. If it's a question, it just answers, with no edit attached.
Recognition runs in two passes. A fast keyword match handles common requests, and anything ambiguous falls back to the connected LLM. A graph edit returns with a confidence score, so a low-confidence guess reads as a guess, not a silent edit. A question like "explain this workflow" doesn't get a confidence score at all, since there's nothing uncertain about answering it, and nothing to apply or reject.
Each proposed edit carries a percentage. A 95% match to "add an approval gate node" looks nothing like a 40% guess at an ambiguous request.
Structural changes, like adding an approval gate or deleting a node, go through the same confirmation step a person already expects from the workflow itself. The copilot proposes. It doesn't commit.
The copilot keeps conversation history, so "no, require two approvers" refines the last suggestion instead of starting over.
The copilot also handles more than single edits. Describe a full workflow instead of one change, "draft a recall notice, require a compliance manager to approve it before filing with CPSC, then notify affected customers once it is filed," and it plans a complete graph against the same node library, builds it with the same node and edge primitives the six shipped templates use, and closes any gap a model leaves open, a rejected branch with no ending, an empty decision condition, before the result reaches the same four validation layers as anything else in the workflow. It's still just a normal suggestion: confidence score, Apply or Reject, nothing commits on its own.

The repair loop isn't a fallback for a failed plan. Models reliably wire the main path of a workflow but leave the unhappy path open, an approval rejection with nowhere to go, a decision with no condition set. That loop catches exactly that gap and closes it before the graph ever reaches validation, so what an operator sees to approve is already structurally complete.
The copilot can also be asked a regulatory question directly, with nothing to build or explain. "What does CPSC 1115 require for a corrective action plan" calls the same regulatory agent Validate and Audit use, not a separate lookup, so an operator gets the same grounded citation a reviewer would see on the approval screen without leaving the graph editor to go find it.
That same review looks backward too. Once a campaign closes, the copilot can look at how it actually ran, where a step took longer than expected, where an approval bounced back more than once, where a step never needed a person at all, and suggest what to change before the next one. It's still just a suggestion the operator reviews like anything else the copilot proposes, but it turns the audit trail from a record of what happened into a working list of what to fix next time.
Before that suggestion becomes a real change, it doesn't have to be trusted on faith. The same testbed used to compare agent versions can replay a workflow against real data from a closed campaign, or against synthetic data built to resemble one when no exact precedent exists, so a team can see whether the suggested change would genuinely have finished faster or cost less before it ever touches a live recall. In a regulated process, a workflow change that turns out wrong risks real delay, real cost, and real fines, so testing it against history or a realistic simulation first is worth far more than shipping it on a guess.
Every graph, hand-built or copilot-suggested, runs through the same checks. The limits live in the platform, not in any one agent's prompt.
Structural checks whether the graph is well-formed. Semantic checks whether the connections actually make sense. Regulatory checks it against the applicable recall standard. Accessibility checks that a person can still perceive and reach every part of a graph an agent just built, an ARIA label on every node, a real keyboard path from trigger to termination, so a copilot-added node never wires in something the next reviewer can't see or get to.
A permission engine checks workflow, execution, and node-type access before any action runs, so a viewer can't approve a recall and a regional admin can't touch another team's workflow.
Validate, Audit, and the copilot all cite the specific standard and section they used, such as CPSC 1115 or FDA 21 CFR Part 7, through the same regulatory agent, instead of relying on memorized language. That citation travels with the output into the audit trail.
Validation isn't a single save-time gate. It runs continuously while a workflow is being edited, a few hundred milliseconds after the last change, so the same four checks a save would run are already visible before anyone tries to save. Errors block. Warnings and lower-severity notes don't, so a workflow can ship with a known, accepted gap instead of forcing every imperfection closed before anyone can move on. Execution itself only re-checks the structural layer, not all four, since a graph that already validated clean at design time doesn't need the slower regulatory and accessibility passes run again on every single run. That tradeoff favors runtime speed once a graph is already known to be sound.
AI can recommend actions, draft outputs, and flag risk. A person still approves key recall steps. That is the default level of automation for this concept.
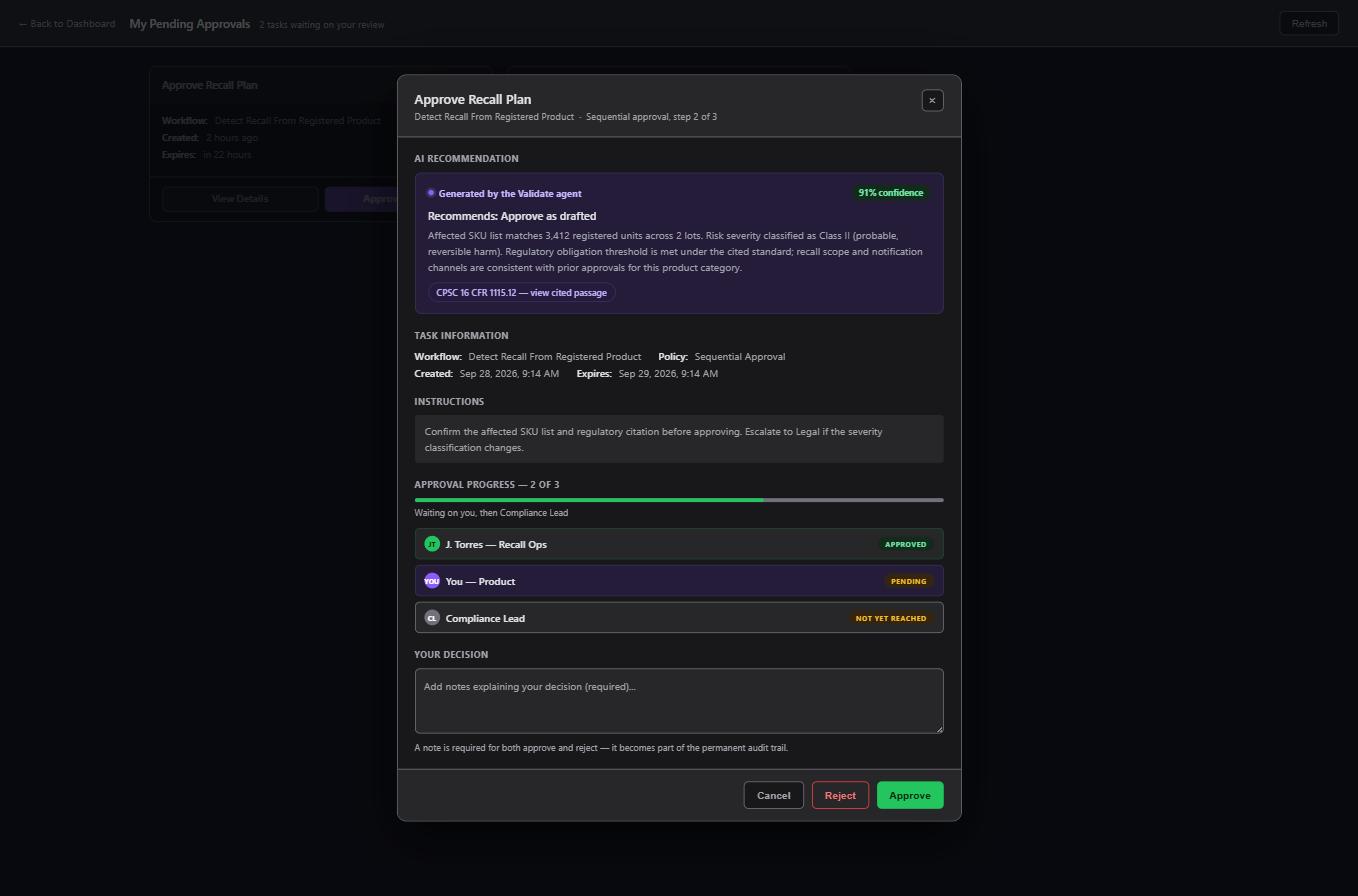
The approver sees the AI's recommendation, its confidence, and the citation behind it, along with where the request sits in the approval chain. Nothing applies itself. Approving or rejecting requires a note, and that note goes straight into the audit trail.
The same note also feeds back into the model. Real decisions, with real reasoning behind them, become training data, so the system picks up nuance over time instead of staying fixed at whatever it shipped with.
Different steps can use different levels of automation. Safety and regulatory actions stay closer to human approval.
The system should only act on approved data sources and structured evidence, not vague or unsupported claims that invite hallucination.
Each role defines what it may decide, what it may suggest, and what it must never do on its own.
Those limits make the concept testable. Teams can review exactly what an agent is allowed to do before it's connected to production work.
The same pattern holds in a real integration. The comms agent can draft and propose a customer-notification campaign, but a separate system, not RMGE, owns the consumer list. Releasing the campaign needs the same approval permission twice, once to approve the draft and again to dispatch it. RMGE never receives a customer name or email address, only an aggregate delivery result for the audit trail.
Analysts told us in research that the status of an active campaign usually lives in a spreadsheet someone updates by hand. This screen is the direct answer. Every KPI a program manager actually gets asked about sits in one place, grouped by what it's for instead of scattered across systems, at a glance, customer response, financial, and physical operations.
The notification funnel ends in a claim-conversion number, not just a click-through rate. Reach, opened, and clicked describe the email. Completed describes whether the owner actually finished the claim. That conversion number is close to, but not the same as, the recall effectiveness rate shown above it, since effectiveness counts every unit remedied through any channel, phone and in-store included, while conversion only counts what happened through this one notification. The screen says so directly instead of leaving two similar-looking numbers unexplained.
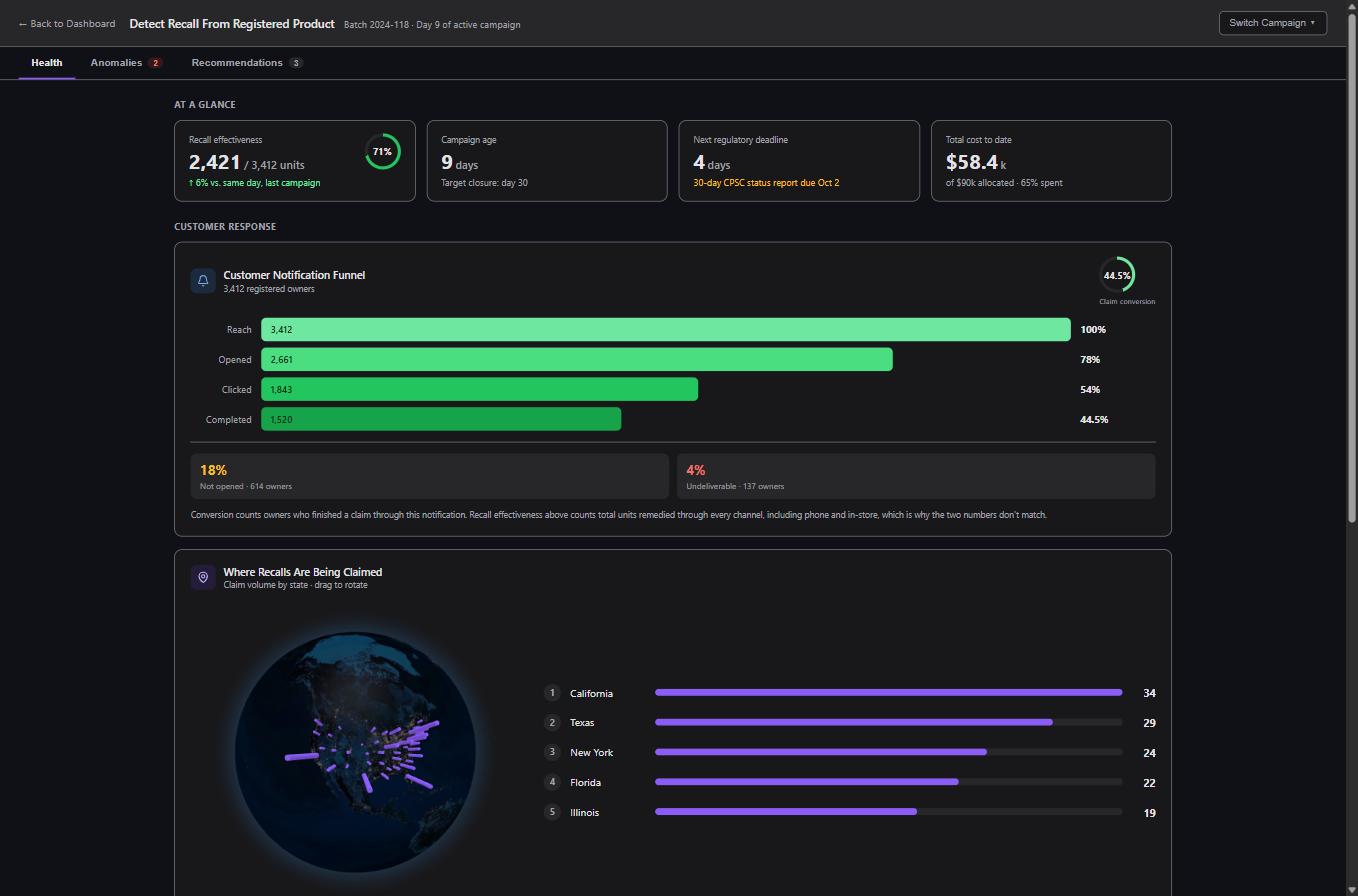
Where recalls are being claimed runs on a real, interactive globe, not a static image, built with the same open-source globe.gl library other analytics products use for this exact kind of geographic volume data. Claim volume by state shows up as a bar rising off the surface, taller where more owners have claimed, next to a plain ranked list of the top five states for anyone who would rather read numbers than rotate a globe.
Financial and physical operations follow the same idea. A refund budget burns down against its allocation, and a full cost breakdown reconciles it against logistics, comms, and destruction so the total matches the one number leadership actually asks for. Destruction status, retailer shelf pull-through, and the logistics pipeline track physical units through the recall the same way, awaiting shipment through delivered, broken out by carrier so a slow last-mile leg is obvious instead of buried in an average.
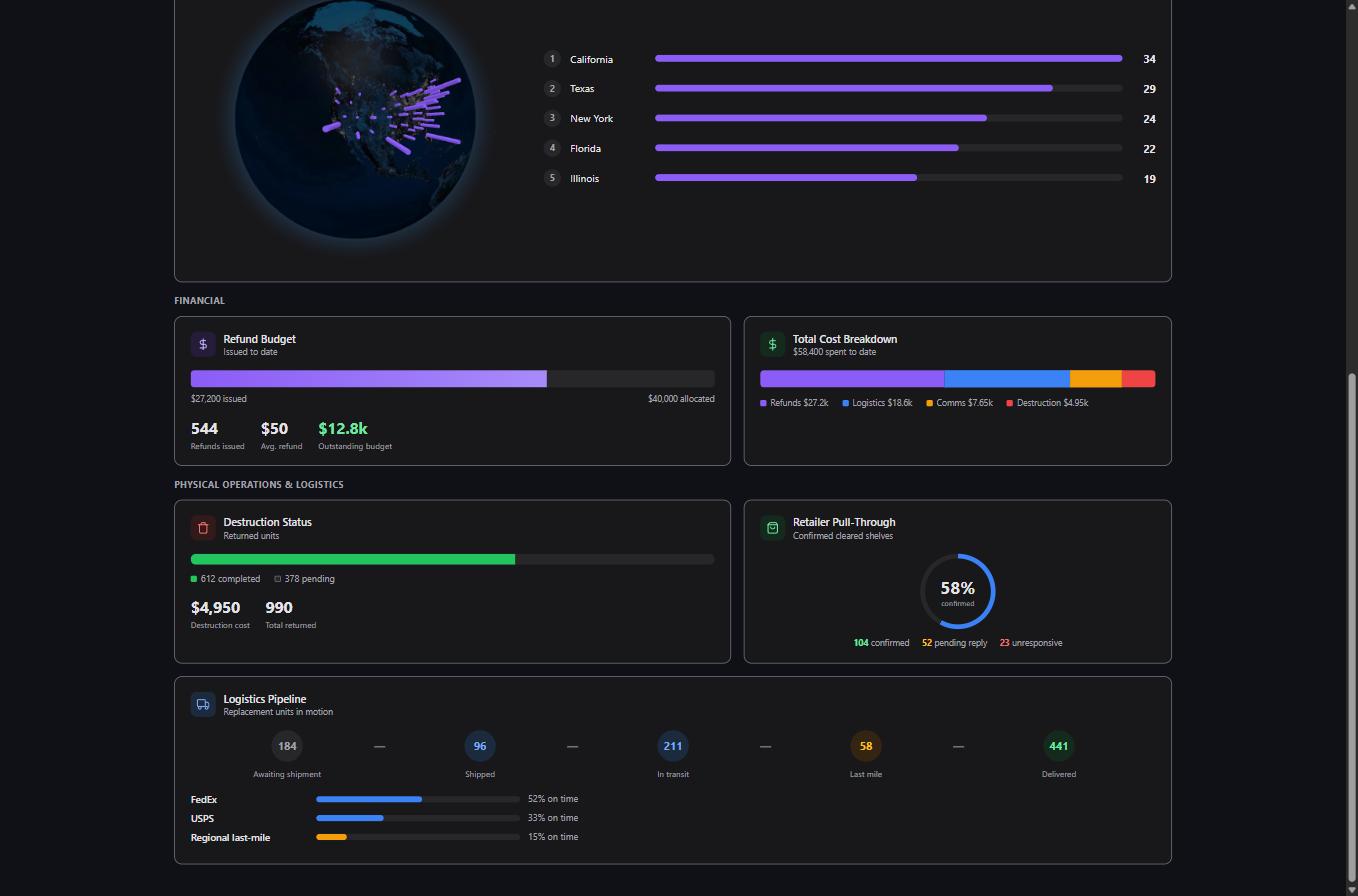
Two more tabs sit behind this same screen, anomalies and recommendations, running the same detect-then-suggest pattern as the copilot's post-campaign review and the program health agent, just scoped to this one campaign in real time instead of a pattern across many. An undeliverable spike or a refund pace running ahead of budget shows up as an anomaly the moment it happens, each with its own suggested fix an operator can apply or dismiss, not a report someone reads after the campaign has already closed.
Agent changes, and copilot-suggested workflow changes, should be tested in a controlled environment before they reach production. Teams can replay a completed campaign's real data, or a synthetic run built to resemble one, against a revised workflow, compare versions, review logs and metrics, and decide whether to ship, revise, or discard a change.
A separate test environment lowers risk and shows whether a change actually improves the workflow.
Teams can judge agent behavior against defined outcomes instead of relying on general confidence in the model.

Our researcher ran a moderated round in the testbed with six internal reviewers, recall ops, compliance, and customer support, across three recall scenarios. Approving a recall plan dropped from an average 38 minutes in the current spreadsheet-and-email process to under 12 minutes end to end. Reviewers accepted the AI's recommendation as-is in about two-thirds of cases and edited or rejected the rest. Every rejection carried a reason, the same audit trail the workflow already depends on.
The same environment is where a copilot-suggested workflow change earns trust before it ships. A sandbox comparison replays a closed campaign's real data against the candidate workflow and reports the delta directly, duration, cost, manual approval steps, and whether compliance checks still all pass, so promoting a change is a decision backed by a real replay, not a guess.
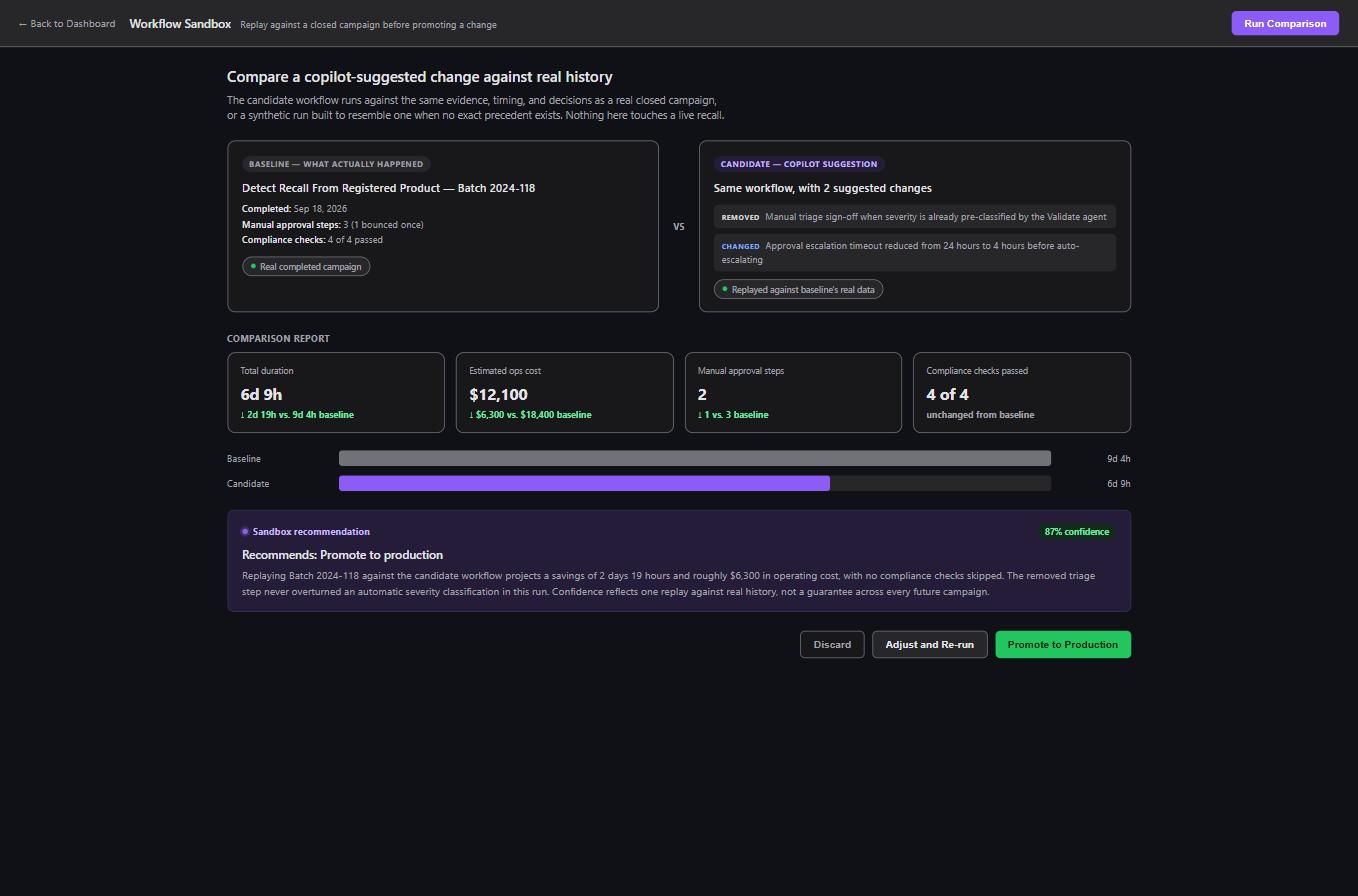
The first version of the approval screen only showed the AI's confidence score after a reviewer had already decided. Testers said they wanted it before deciding, not after, so the recommendation panel now leads with confidence and the citation, and the decision notes come last.
I started with the recall workflow, then defined where AI could help, what it could do, and where people had to stay in control.
I connected recall stages, evidence, tools, and handoffs into one workflow.
I used narrow roles, guardrails, approvals, and testing so the concept could be evaluated as a real product workflow.
I mapped the recall process first, then added AI, an editing copilot, and guardrails only where they supported that work.
The product depends on how people, rules, tools, evidence, and approvals work together.
AI helped organize workflow notes and research into specifications. I owned the design decisions.
Figma, Photoshop, Illustrator; a React/TypeScript graph engine with a PHP/MySQL service layer for a working interactive prototype; workflow diagrams; agent workflow maps
Codex for coding and QA; I defined agent roles, task types, guardrail layers, and human-approval checkpoints; AI helped organize the documentation
Recall compliance mapping and agent testing rules; AI helped organize my workflow notes and I reviewed the source material myself
Role: IC product designer. I owned the recall workflow, agent roles, guardrail rules, the AI Copilot interaction, human-approval UX, and testing approach. AI helped organize my notes into documentation.
Designed the conversational layer of a workflow builder for regulated recall operations, where a confident-sounding wrong answer or a silent edit is a real compliance risk.
A conversational layer for a compliance-critical workflow builder, where every answer is visibly separate from every edit, and every edit waits for a person.
A graph edit in RMGE, the Recall Management Graph Editor, can add or remove an approval gate on a regulatory filing. A generic "ask me anything" assistant doesn't fit a tool like that. People trust an open-ended chat box more than they should, and here, a wrong click isn't a minor inconvenience.
So the copilot's job is narrower than a typical assistant. It helps someone build and read a graph faster. They can describe a change instead of dragging nodes, or ask what a graph does instead of tracing it by hand. It doesn't make the judgment calls that already go to a person for approval.
I defined how the copilot behaves mid-conversation. It has to ask instead of assume when something's unclear, and any proposed edit needs someone to confirm it before it counts. I also decided how much of the exchange it can remember, and how it shows its confidence, since that's what tells a user whether to trust an answer or double-check it.
Drew the line between "the copilot is answering" and "the copilot wants to change something," and made sure a user could always tell which one they were looking at.
Defined how a keyword match becomes a percentage, and what confidence threshold sends a request past the keyword layer to the connected model instead of guessing.
Routed every proposed edit through the same four validation layers and the same approval pattern the rest of the workflow already used, so the copilot never became a side door around them.
I worked alongside the same ML engineer and AI architect behind the agent workflow, plus a researcher who ran the copilot's early usability rounds. The architect and I had already figured out when calling the live model was worth the cost and delay for the agent roles. I built the copilot's intent recognition the same way: a fast keyword path handles common requests, and the model only steps in when something's ambiguous, instead of routing every message through it by default.
The UX rules behind the interface make the copilot's output trustworthy and traceable to real data. It shows its reasoning, asks a question when something's unclear, and waits for a person to decide before it changes anything.
Most assistant UX assumes a wrong answer is a minor inconvenience, and that chat itself feels low-stakes: ask a question, get an answer, move on. Neither assumption holds here. A confidently-worded wrong answer about what a workflow does sounds right even when it isn't. And without a clear line between "explaining" and "editing," a change could hit a live compliance workflow before anyone notices.
A copilot that can both answer and edit has to make it obvious which one just happened. Otherwise a user only finds out by re-reading the graph, not from anything the interface told them.
A model that sounds equally sure whether it's certain or guessing trains people to stop checking. In a workflow that can touch a regulatory filing, that's a bad habit to build.
"Explain this workflow" and "add an approval gate" aren't the same kind of request. One just reads. One changes something. A flat chat transcript treats them the same way.
Before designing the interaction model, our researcher talked to the same practitioner roles from the workflow case study about their own experience with chat-based assistants elsewhere: workflow authors building their first graph, compliance reviewers approving whatever the copilot proposed, and ops leads running the copilot mid-incident. Their complaints about other tools, not a feature wishlist, drove most of the copilot's interaction rules.
Workflow authors said other tools answered in the same confident tone whether the model was sure or guessing, so they'd learned to ignore the tone entirely and double-check everything. This is why every proposed edit here comes with a visible sign of how confident the match was, instead of a flat "done."
First-time users described staring at an empty chat box, unsure what the assistant could actually do, then giving up and building the graph by hand anyway. This is why the copilot panel opens with suggested starting prompts instead of a blank field.
Users who'd tried multi-turn edits elsewhere said a correction like "no, require two approvers" usually meant starting over, not refining anything. This is why the copilot keeps conversation history and treats a follow-up as a refinement of the last suggestion.
Compliance reviewers said a wrong suggestion wasn't the scariest part. Not knowing whether a suggestion had already changed a live workflow was worse. This is why a proposed edit always waits for an explicit Apply, the same confirmation step the rest of the workflow already required.
Ops leads said other tools would just guess at an unclear instruction and act on the guess. This is why an ambiguous request here falls back past the keyword layer to the connected model, and comes back showing lower confidence instead of a false one.
Reviewers said dismissing an AI suggestion elsewhere left no trace of the reason. An audit finds that kind of gap later. This is why rejecting a copilot suggestion uses the same required-note pattern as any other approval decision in the workflow, so the reason goes into the audit trail either way.
Two rules shipped in the first build and never moved: never apply anything silently, and make an answer look different from an edit. The pilot never gave us a reason to touch either one.
The third rule didn't make it through unchanged. That first build showed confidence as a percentage in the chat, the same pattern most AI tools use. Reviewers said it still felt disconnected from the graph itself, they'd read a number in the sidebar, then go find the node it was actually talking about. That's what forced the redesign: confidence had to live on the node, not in a badge next to it.
A fourth rule got added on top of that, for a different reason. A low-confidence percentage told a reviewer something was uncertain, but not what to do about it. Most people just retyped the request from scratch instead of figuring out what the copilot had actually been torn between. So an uncertain node needed its own fix, not just its own warning.
A proposed edit sits and waits until a person accepts it. Nothing changes on its own, no matter how confident the match.
A plain answer and a proposed edit use different visual treatment, so a user never has to guess which one they're looking at.
A proposed node renders dashed, not solid. Confidence is something you see on the graph itself, not a percentage tucked in a sidebar.
An uncertain node offers real candidates to pick from, or a person can correct it directly. Either way, that correction goes to a person before it ever touches the model.
The result is a copilot that shows its own uncertainty on the graph, and always gives a person a way to resolve it.
Every message goes through the same two-pass check. A fast keyword layer handles common requests, like "add an approval gate node" or "connect these nodes," and matches most of them in one pass. Anything it can't match confidently falls through to the connected model instead of guessing.
The result is always one of two things. A question gets a plain answer in the chat, nothing to apply or reject. A request that changes the graph gets a new state on the canvas instead: the node renders dashed, purple when the match is confident, amber when it isn't.
An amber node doesn't just sit there uncertain. Clicking it surfaces the copilot's actual candidates side by side, so a person picks the right one instead of reading a percentage and hoping.
Common requests match fast and cheap, without waiting on a round trip to a model.
An ambiguous request only reaches the connected model when the keyword layer can't confidently match it.
A question returns a chat answer. A change returns a dashed node on the graph. The two never look the same.
The same pipeline handles more than one small edit at a time. Describe a whole workflow instead, and the copilot plans a full graph using the same node library the rest of RMGE uses, then runs a repair loop that closes gaps a model tends to leave open, like a rejected branch with no ending, before the result ever reaches validation.
Whether it's one node or a whole graph, the result still comes back the same way: every node it touches renders dashed, and a person still has to approve it before it counts.
The copilot isn't one generic chat feature. It does five distinct things: explain, edit, compose, cite, and review. Each one behaves differently, instead of all five being treated like the same kind of chat message.
Describe a whole path, draft a notice, require approval, notify customers once it's filed, and the copilot plans it using the same node types and validation as a graph built by hand.
A regulatory question doesn't need a separate lookup. Asking the copilot what a standard requires calls the same regulatory agent Validate and Audit already use, so the answer comes with the same grounded citation a reviewer would see, plus a Show me action that jumps straight to the node it applies to.
Once a campaign closes, the copilot can look back at how it actually ran. It can flag where an approval bounced back more than once, or where a step never needed a person at all, and suggest what to change next time. It's still just a suggestion someone reviews like any other.
Every copilot suggestion, however it's phrased, still has to pass the same four validation layers as a hand-built graph: structural, semantic, regulatory, accessibility. The conversation doesn't get a shortcut around them.
Three problems are specific to a copilot, though. A model can wire the main path of a request and still leave the rest open, like an approval branch with nowhere to go if it's rejected. A suggestion that looks structurally fine on paper might not actually help once it runs against a real recall. And a correction from one reviewer can teach the system something wrong just as easily as something right.
Before a copilot-built graph ever reaches validation, a repair pass closes the gaps a model tends to leave, like an approval with no rejection path or a decision with no condition set. What a person sees to approve is already complete.
A proposed edit sits in a waiting state until a person accepts it, whether it came from a keyword match or a full workflow the copilot planned on its own. That decision becomes part of the node's own history, not just a log entry somewhere else.
A copilot-suggested change can run in the same sandbox used to test hand-built changes, replayed against a closed campaign's real data, so a team can see the actual delta in duration, cost, and compliance before it ever touches a live recall.
Rejecting a suggestion can include a correction, but that correction goes into a review queue for an ML engineer to curate. It never trains the model automatically, so one bad correction can't quietly teach the copilot the wrong lesson.
None of this is a special conversational exception. It's the same four validation layers and the same approval pattern the rest of the workflow already uses. The copilot just isn't allowed to be the shortcut around them.
Every rule from the last two sections is something you can point to on the canvas. Here's what a proposed edit, an ambiguous request, a focused review, and a correction actually look like, not just described in a chat window.
This is the redesigned version, not the first build described in Strategy.
We ran a six-week pilot with four recall ops teams on that first build, the one with a confidence percentage in the chat, turned on for real draft workflows. Over that stretch it reviewed 812 proposed edits across 34 workflows, enough usage to see whether the badge actually held up outside a demo.
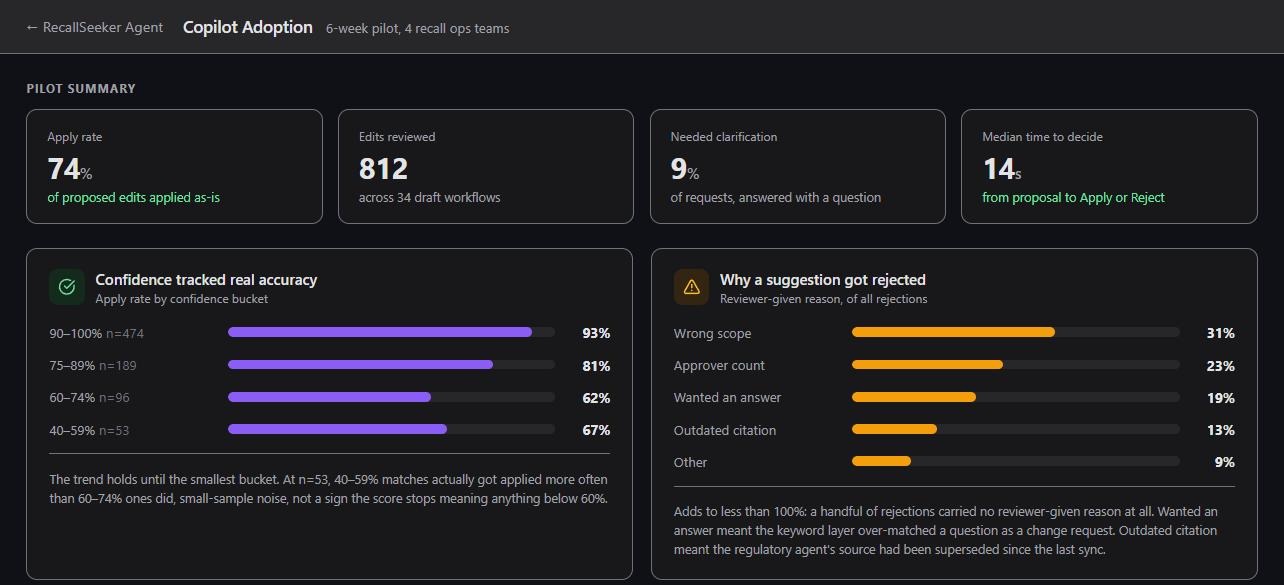
The confidence score mostly held up. Edits above 90% confidence got applied almost every time, and that pattern held cleanly all the way down to 60%. Below that, something odd showed up: the 40–59% bucket actually got applied more often than the 60–74% bucket right above it. That bucket only had 53 edits in it, small enough that one busy week could swing the number. It doesn't mean the score stops working below 60%. It means there isn't enough data yet to be sure either way.
The rejection reasons turned up two problems the pre-launch interviews hadn't caught, because they only show up once real people are using real drafts. "Wanted an answer" meant the keyword layer was over-matching some questions as change requests. "Outdated citation" meant the regulatory agent's source had been superseded since its last sync, so it kept citing a rule that was no longer current.
The over-matched questions went into the same review queue a correction uses now, an ML engineer curated them into training examples for the question-vs-edit split, so a request that only sounds like an edit is less likely to get treated as one.
The regulatory agent flags a citation as possibly stale instead of quietly repeating it, so a superseded rule doesn't keep showing up in a proposed edit or an approval screen.
None of that mattered as much as the one complaint reviewers kept repeating: they had to go find the node a percentage was talking about. That's what forced the redesign in the sections above. These fixes shipped inside the badge-based version first. The node-native version replaced the badge itself.
I started with the rules a copilot in this kind of tool could never break, then designed the conversation around them: what it can say, what it can propose, and when it has to stop for a person.
Built a copilot that does five different things: explain, edit, compose, cite, and review. Each response type has its own visual style, so users can tell them apart at a glance.
Started with a percentage in the chat, then redesigned it as a dashed-to-solid state on the node itself once the pilot showed the badge wasn't enough.
An uncertain node offers real candidates to choose from, so the copilot asks instead of guessing.
Built the review queue an ML engineer curates before anything a reviewer corrects becomes a training example.
The product depends on the copilot knowing the difference between answering and acting, and on a person always making the call when it matters.
AI helped organize research and interaction notes into specifications. I owned the design decisions.
Figma, Photoshop; a React/TypeScript copilot panel prototype with a PHP/MySQL service layer; conversation flow diagrams; the node-native confidence states, candidate picker, and Focused Review Mode shown above
Codex for coding and QA; I defined the interaction rules, the confidence model, and the guardrail integration; AI helped organize the documentation for developer handoff and validation
Practitioner interviews on conversational-AI pitfalls, conducted with a senior researcher; the six-week adoption pilot; I reviewed the source material myself
Role: IC product designer. I owned the conversation design, the confidence model, the guardrail integration, and the changes that came out of the pilot. AI helped organize my notes into documentation.
Redesigned time and attendance around an actionable hub, exception-first workflows, batch processing, and worker participation so managers could return to frontline work.
Making time anomalies faster to review and easier to act on
Time Anomalies was part of Workday's Frontline Manager Experience. The goal was to reduce the time managers spent chasing time sheet errors, approvals, and attendance exceptions so they could get back to their teams.
I led the feature design end to end and helped define the surrounding workflow, integration points, and mobile support. The final experience showed what needed attention, automated simple approvals, and reduced one-worker-at-a-time correction work.
I was the design lead for the feature across product areas and platforms. I defined the main workflow, mapped integration points, and identified where anomaly detection and automation could remove repetitive work.
Mapped a frontline manager's day to understand when time management work actually happened and what needed attention first.
Defined the anomaly detection, review, approval, and exception-handling flows across web, while supporting direction for the mobile designer.
Mapped how Time and Attendance connected with Scheduling, Payroll, HR, Reporting, and planning products so the workflow stayed connected.
The work covered the screens, the connected systems, and the points where the product could remove or create extra work.
Frontline managers spent too much time finding and fixing time sheet errors, handling approvals, and chasing missing entries. Some worked weekends and overtime to keep up with vacation requests, attestations, and corrections.
Every hour spent on repetitive time administration pulled managers away from the floor and their teams.
Managers often had to move employee by employee just to review, correct, and submit time.
Managers had a hard time seeing critical attendance and approval issues quickly, especially at the start of a shift.
Managers were doing administrative cleanup instead of spending time with workers and operations.
Research included frontline managers, HR, time administrators, key customers, and early adopters across retail, hospitality, food service, and manufacturing. The main issue was how fragmented the manager's day already was.
Managers wanted useful information earlier in the day. The product needed to show what was wrong, what was urgent, and what could be completed quickly without digging through several views.
I designed the feature around managers who juggle operations, staffing, finance, and people work at the same time.
No single team had a complete view of all the connected product areas, so I helped map those dependencies.
The common case needed to be fast, while labor and compliance exceptions still needed full support.
The day-in-the-life map showed where time management fit into the first 60 minutes of a shift and how it connected to operations, finance, and HR work later in the day.
The workflow followed three rules. Use the existing Time Management Hub. Show actionable counts and exceptions up front. Automate simple approvals so managers only review what needs attention.
Show what needs attention during the first part of the shift before the manager has to search for it.
Managers with large teams need filters, grouping, and batch actions. Reviewing one worker at a time is too slow.
When appropriate, workers should be able to correct or confirm their own information instead of routing every issue through a manager.
The hub gave managers a starting point. Anomalies identified what needed review. Batch processing handled the common case. Analytics showed broader workforce patterns. Together, the pieces reduced time spent hunting for work.
Show what needs review, what is urgent, and where the manager should go next.
Use visible counts and simple filters to move from awareness to action without repeated query setup.
Show broader labor, attendance, productivity, and operations patterns from the same product area.
Batch processing removed the need to open workers whose time sheets had no problems. Managers could approve the common case together and spend their time on real exceptions.
Workers could provide attestations, time events, or corrections closer to when the issue happened. That reduced the amount of reconstruction managers had to do later.
Workers can provide information earlier, which reduces the manager's need to reconstruct what happened after the fact.
Workers and managers can resolve an issue together instead of relying on a one-sided correction.
Capturing events closer to when they happen improves data quality and reduces cleanup work later.
ML was still new in Time and Attendance, Scheduling integration was being built in parallel, and labor rules varied by state and country. The work also crossed several product areas, so validating ownership and integration points took time.
Anomaly detection had to account for labor rules, grace periods, exceptions, and regional differences.
No one person had a complete map of the connected systems, so part of the design work was getting the right teams aligned around the dependencies.
Automation removed manual review for qualified zero-error time sheets. Every early adopter partner renewed after release. The workflow expanded from retail into hospitality and food service, with manufacturing customers also showing interest.
Rules removed manual review for qualified zero-error time sheets, creating a zero-touch path for the common case.
100% of EA partners renewed once released.
The solution extended beyond its original retail focus into adjacent frontline-heavy industries.
I used day-in-the-life research, exception-first review, and cross-product integration to reduce repetitive enterprise work.
I connected the hub, detail views, exceptions, and worker input into one workflow.
I focused on the parts of the workflow that cost managers the most time, especially large-team approvals.
I helped define integration points across several product areas and kept the workflow consistent across them.
The shipped workflow reduced time spent on time administration and gave managers more time with their teams.
The work covered research, workflow design, prototyping, design-system patterns, and implementation review.
Figma, Photoshop, PHP, MySQL
User interviews, journey mapping, workflow analysis, usability testing
Jira, Confluence for specs and handoff; worked directly with engineering during implementation
Role: I was the IC design lead and mentored other designers on research synthesis, interaction design, prototyping, specifications, and design validation through release.
Extended the Double Diamond with a formal outcome-learning space that connects delivery, telemetry, experimentation, and strategic feedback.
A design framework that adds post-launch learning to the Double Diamond and shows where AI can help without replacing product judgment.
The Triple Diamond adds a third space to the Double Diamond. Diamond 1 defines the problem. Diamond 2 tests the solution. Diamond 3 measures what happened after launch and feeds that evidence back into the next round of discovery.
The framework gives teams one view of the work before and after launch. Product data, experiments, customer feedback, and decision logs connect shipped work to the next product decision.
The Double Diamond gives teams a clear structure for discovery and solution design. The third diamond adds a defined place to compare what the team expected with what users actually did after launch.
After launch, product data and customer feedback become inputs to the next design decision.
Teams can compare design decisions with observed behavior, customer feedback, and the success criteria set before launch.
Leaders can see how design decisions connect to product outcomes and what the team changes next.
The third diamond defines how teams collect post-launch evidence and turn it into the next product decision.
The first diamond starts with user signals, research, and product data. The team groups the evidence, defines the problem, maps the opportunity, and sets success criteria. Assumptions stay labeled as assumptions until they're tested.
Every problem statement should point back to a user signal, product metric, or research finding.
Edge cases and different user needs should be part of the problem definition from the start.
The team writes assumptions as hypotheses to test.
Teams can move into solutions too quickly, respond to the loudest symptom, or treat assumptions as evidence. Diamond 1 gives the team time to understand the problem before committing to a direction.
The second diamond explores possible solutions and tests them. Usability testing checks whether people can use the design. Engineering review checks whether the team can build it within scope. Accessibility review checks the interaction before handoff.
Testing gives the team something stronger than preference to base the decision on.
Product and engineering review platform, scope, and implementation constraints before the direction is final.
Accessibility requirements are part of the interaction and component rules before QA.
Testing includes errors, empty states, edge cases, and content. The main path alone isn't enough.
After launch, teams track product behavior, review funnels and cohorts, run experiments, and collect customer feedback. That evidence informs fixes, backlog priorities, and roadmap changes.
Each change should link back to the metric or finding that triggered it.
Teams define hypotheses and success criteria before launch so they know what to measure.
Post-launch findings should feed directly into the next problem-framing cycle.
Post-launch measurement matters when it changes what the team fixes, tests, or prioritizes next.
Specialist agents can watch defined product signals such as onboarding, retention, feedback, usage, and reliability. They collect and organize evidence, then prepare a brief for human review. The product team still decides what the evidence means and what to do next.
Each specialist watches one area such as customer feedback, onboarding, retention, usage, or reliability using approved sources and thresholds.
The system removes duplicates, links related findings, and keeps the source behind each one.
The system summarizes reach, severity, confidence, risk, and effort. The product team makes the decision.
The product team decides whether to test, fix, reprioritize, or send the finding back into discovery.
Clusters themes across support conversations, surveys, reviews, and research follow-ups, then connects recurring concerns to product behavior.
Monitors completion, abandonment, repeated errors, and time to first value across releases and user cohorts.
Shows changes in cohort retention, engagement frequency, incomplete value loops, and related customer feedback.
Identifies feature adoption, unexpected paths, repeated workarounds, and capabilities that users don't discover.
Tracks error rates, failed actions, crashes, latency, and behavioral changes associated with a release or affected segment.
A tool such as Jira can turn a reviewed finding into an issue with evidence, affected users, severity, reproduction steps, and an owner. The team can then assign a low-risk issue to a coding agent. The agent works in its own branch, runs the required checks, and opens a pull request. It can't merge the change.
Complex, ambiguous, sensitive, or high-impact work stays with people. Low-risk work still requires human code review before merge. Branch protection, required checks, limited permissions, audit logs, and reversible changes enforce that boundary.
Narrow, reproducible, reversible issues with clear acceptance criteria and limited dependencies.
Unit and integration tests, linting, accessibility checks, security analysis, and any repository-specific validation.
A person reviews the evidence, code, test results, and product impact before approving the pull request.
AI can help with different tasks in each diamond. In Diamond 1, it can group themes and find patterns in research or product data. In Diamond 2, it can help draft design variants, content, and accessibility checks. In Diamond 3, it can flag unusual behavior and organize post-launch signals for review.
Use AI where the task is clear, the output can be reviewed, and it saves manual work or expands coverage.
When AI output affects a product decision, keep the source evidence, review history, and human approval.
The framework maps to a simple review rhythm. Weekly reviews cover product signals, support issues, and defects. Biweekly reviews connect testing and design decisions to metrics. Monthly reviews cover experiment results, lessons, and roadmap changes.
Design, product, engineering, research, and data use the same evidence from dashboards, experiments, decision logs, shipped changes, and follow-up measurement.
The Triple Diamond gives leaders and delivery teams one view of the work before and after launch. It shows how post-launch evidence affects product decisions, where AI can help, and where existing product data and review practices fit.
Product data and analytics become inputs to design decisions.
AI is used for specific tasks with clear review points and limits.
The framework can use product data, dashboards, experiments, and review practices teams already have.
I designed the framework to connect discovery, delivery, and post-launch learning. The goal was to make the process specific enough for teams to discuss, test, and use in their existing product workflow.
The model shows where design decisions are made, what evidence supports them, and what happens after launch.
Each diamond maps to a review rhythm, evidence, outputs, and team responsibilities.
The diagrams make the relationships between process, evidence, and decisions easier to understand quickly.
The framework combines user research with measurable product outcomes. People still interpret the evidence and make the decisions.
This was design leadership work focused on process design, visual communication, and cross-functional review.
Figma, Photoshop, and Illustrator for framework diagrams and workflow visualization
Post-launch learning, evidence-based decisions, and AI review points
Framework documentation, cross-functional workshops, stakeholder presentations
Role: Design lead. I developed the framework, created the visual models, defined the team workflow, and used it to support cross-functional discussion.
Open to principal and senior product design roles, including design leadership.
I'm looking for senior IC or design leadership roles focused on complex workflows, strong interaction design, and close collaboration with engineering. My strongest fit is enterprise SaaS, responsible AI, design systems, and 0-to-1 products. I value teams that take accessibility and inclusive design seriously.
If you're building a complex product and need a designer who can connect user needs, system behavior, and implementation, I'd be glad to talk.